Quick answer:
An enterprise data warehouse (EDW) used to be one big system bought from a vendor such as Oracle, SAP or Teradata. It held the company’s historical data for reporting and business intelligence.
Today, the same job is done by a stack of layers: storage, often cloud object storage, followed by integration and ingestion, processing in a cloud warehouse such as Snowflake, BigQuery, Amazon Redshift or Databricks, and analytics and BI on top. Teams can pick a tool for each layer and automate the pipelines between them.
Enterprise Data Warehouse Definition: Then and Now
What is an EDW?
Historically, the Enterprise Data Warehouse (EDW) was a core component of enterprise IT architecture. It was the central data store that holds historical data for sales, finance, ERP and other business functions, and enables reporting, dashboards and BI analysis.
Today, the definition of the EDW has expanded. It has become a “stack”, not a monolithic system you build and maintain.
EDW as Monolithic Enterprise System
To many organizations, the EDW is a corporate system made up of several components:
- Central Enterprise Data Warehouse from vendors like Oracle, SAP and Teradata.
- Data marts deployed in specific departments containing a subset of organizational data. While data warehouse theory suggested either central EDW or individual data marts, in reality many organizations combine models and have both.
- Online Analytical Processing (OLAP) server that processes complex queries on the data.
- Extract Transform Load (ETL) software from vendors like Informatica, which automates complex data pipelines.
- BI and reporting tools received structured data from the data warehouse and used it to produce reports and visualizations of business metrics.
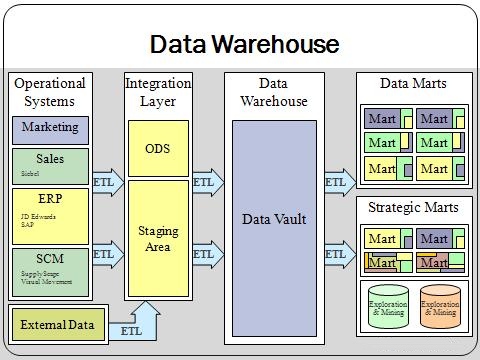
This is the old definition of EDW: it views the Enterprise Data Warehouse as a rigid, monolithic system that is built once and maintained. It “does what it does” and cannot evolve to support other needs or new types of data. By definition it is a big, heavy and expensive piece of infrastructure.
EDW as a Stack: Out with Complexity, No Need for Details
Think of a personal computer. There is a technology stack that powers our experience, from motherboard, CPU and disk storage, through to BIOS, operating system, and specific applications.
The higher up a component is in the stack, the more we as users care about it. We don’t care what version of BIOS we are using, and it’s less important to us if it’s Windows 10 or Windows 11. We start caring at the application layer, for example if it’s Microsoft Word or Google Docs. We don’t need to understand or even know about the lower layers of the stack. They are transparent and taken care of for us.
Today, organizations just “don’t care” about the inner working of an EDW. They want a solution that manages data and derives insights. Things like ETL, OLAP and storage engines are like the BIOS to them: they should simply work and they don’t want to worry about it.
Hadoop and data lake technology, which were at one point considered an alternative to the traditional Enterprise Data Warehouse, are now understood to be only part of the big data stack. You can’t replace an EDW with Hadoop, but you can replace the monolithic storage and data processing elements of an EDW with next-generation technologies. Today that usually means cloud object storage such as Amazon S3, open table formats such as Apache Iceberg, and a cloud data warehouse or lakehouse engine on top.
Here is our view of the big data stack.
- The top layer, analytics, is the most important one. Analysts and data scientists use it. It’s not part of the Enterprise Data Warehouse, but the whole purpose of the EDW is to feed this layer.
- The lower layers, processing, integration and data, are what we used to call the EDW. These are technology layers that need to store, bring together and process the data needed for analytics. Old EDW technology can still function in these lower layers. Or it can be replaced by cloud-based technology that is easier to set up and manage.
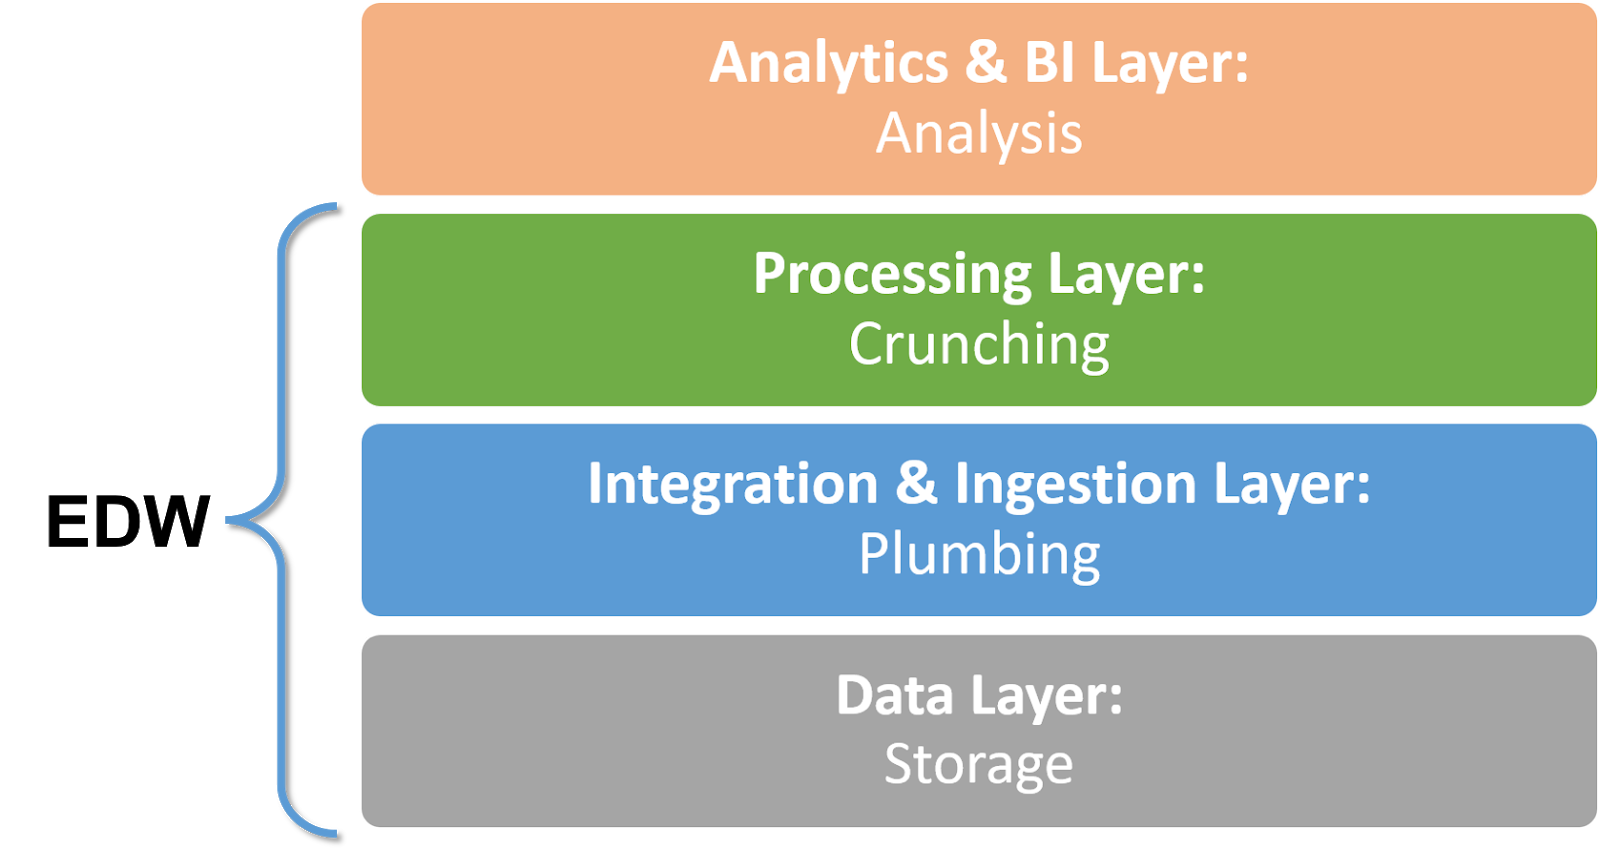
The industry now calls this layered approach the modern data stack. It usually adds a transformation step that the diagram folds into integration: raw data is modeled into clean tables inside the warehouse after loading.
The New EDW: Layers and Technology Options
According to our view of the EDW as part of the big data stack, here are the technologies that organizations can pick and choose to build their stack.
Data Layer
Today many organizations manage petabyte-scale data. The requirements are to store massive amounts of raw data, and not just Online Transaction Processing (OLTP) style data like in the old EDW: semi-structured and unstructured data is growing in importance.
The data layer can be:
- On-premises: raw data stored in relational databases like PostgreSQL or MySQL, NoSQL databases like Cassandra or MongoDB, which can also handle unstructured data, or for very large data, Hadoop HDFS.
- In the cloud: data stored using services like Amazon S3, Amazon Elastic File System (EFS), Amazon Elastic Block Store (EBS), and Azure Blob Storage.
- Open table formats: Apache Iceberg and Delta Lake add transactions, schema changes and time travel to files in object storage. Snowflake, BigQuery, Redshift and Databricks can query the same Iceberg tables, a basis for the data lakehouse.
Integration and Ingestion Layer
This layer adds new data into the data layer, and combines data in ways that are meaningful for analysis. Instead of a heavy ETL process that is meticulously designed and tested, for specific data and information flows, this is a flexible system that can add data to the flow and juggle it around to suit current business requirements.
The integration layer can be based on:
- Traditional ETL systems, like Informatica and Talend.
- Cloud-based ETL and ELT services, like Fivetran, Airbyte and Stitch. These tools can pull in data sources, both cloud-based and on-prem, in a matter of minutes, set up transformations and pipe the data back to the data layer for storage, to data warehouses for processing and ongoing reporting, or directly to BI tools.
- Change data capture and streaming: tools like Debezium read a database’s change log and send each insert, update and delete onward, often through Apache Kafka. This change data capture approach can keep the warehouse minutes or seconds behind the source.
With ELT, cloud teams load raw data first and transform it inside the warehouse with SQL, rather than transforming before loading as classic ETL does. dbt handles that transformation step. Fivetran and dbt Labs completed their merger on June 1, 2026, putting a major managed-connector service and dbt under one company.
Processing Layer
This is where the data warehouse itself lives, tasked with taking all the data, structuring it into a format suitable for OLAP and SQL queries, optimizing it, and handing it over to analysis tools.
The processing layer can be based on:
- Old style EDW products like SAP BW and Teradata EDW.
- Cloud-based data warehouses like Amazon Redshift, Google BigQuery, Snowflake and Databricks. These are offered on a pay-per-use basis, requiring no upfront investment, and scale storage and compute separately, well beyond what most on-premise data warehouses can reach.
It’s not either-or. Just like in a data mart strategy, an organization can maintain several data warehouses. For example, use an on-premise system for sensitive data with compliance requirements, and use cloud-based systems for other data.
Analytics & BI Layer
Although analytics and BI are not strictly part of the EDW, in this extended view of the data stack, they should be. We suggest that the broader EDW stack should also contain big data analysis and visualization tools:
- Data extraction and parsing tools: can make sense of large volumes of unstructured data, such as scraped website data. Examples are OpenRefine and Import.io.
- Sentiment and language analysis tools: can extract meaning from textual content, using techniques like sentiment analysis, entity extraction and clustering. Much of this now runs inside the warehouse as SQL functions, such as Snowflake’s AI_SENTIMENT and Databricks’ ai_analyze_sentiment.
- Data mining tools: used to discover hidden insights in huge volumes of data. Examples are Orange and KNIME.
- Data visualization and BI tools: the “icing on the cake”, allowing analysts and data scientists to explore data and build dashboards and charts answering business questions. Examples are Tableau, Microsoft Power BI and Looker.
A semantic layer, such as Cube, sits between the warehouse and analytics tools, defining metrics like revenue or active customers once so every dashboard uses the same numbers. Reverse ETL tools such as Hightouch provide another path out of the warehouse, sending modeled data back into CRM, support and marketing tools.
Automation in the New EDW Stack
In the new EDW stack, things move fast. Data flows instantly from sources to data storage, is immediately processed by cloud-based data warehouses, and pushed to data analysis and BI solutions. New data sources appear all the time and data volumes continue to grow.
In this environment, there is no time for a team of data engineers to sit down and meticulously plan, test, stage and deploy data transformations, as they would do for months in a traditional EDW project. Organizations need the data now, and they need it to be cleaned, high quality and in a structure that facilitates analysis.
The solution is data warehouse automation. The new EDW, composed of all the types of tools we listed above, should be able to automate all stages of the data pipelines:
- Instant data ingestion: the EDW should ingest data at the click of a button, with no need for large file uploads, format conversions, encoding, schema analysis, etc.
- Automated data cleaning and preparation: the EDW should automatically recognize patterns in the data, remove irrelevant or erroneous data and prepare data for analysis.
- Easy, ad-hoc data transformations: analysts should be able to define their interests and easily transform data, even very large data sets, into a format that facilitates analysis. This should happen in 5 minutes and should not be reliant on data engineers.
Much of this automation now exists, spread across several kinds of tools rather than delivered by one product.
- Managed connectors: Fivetran, Airbyte and the open-source Python library dlt help handle API changes, incremental loads and new source columns, known as schema drift. Supported sources can be added through configuration rather than custom connector code.
- Transformations as code: dbt models are SQL files kept in version control, with tests for uniqueness, nulls and relationships that run on every build.
- Orchestration: schedulers such as Apache Airflow and Dagster run loads, transformations and checks in the right order and retry failures, which is the job of data orchestration.
- Data observability: tools such as Monte Carlo watch freshness, volume and schema changes and alert the team when a table breaks, a practice known as data observability.
Automation removes most plumbing work, but modeling and ownership still require decisions about which tables are the source of truth, how metrics are defined and who owns each pipeline.
The EDW Stack Then and Now
The table below summarizes how each layer has changed from the monolithic EDW to the tools in a modern data stack.
| Layer | Traditional EDW | Modern data stack |
|---|---|---|
| Data | Relational databases, NoSQL stores and Hadoop HDFS on company hardware | Cloud object storage such as Amazon S3, often with Apache Iceberg or Delta Lake tables |
| Integration and ingestion | Hand-built ETL jobs in Informatica or Talend | Managed connectors (Fivetran, Airbyte, Stitch, dlt), change data capture and streaming |
| Transformation | Inside the ETL tool, before loading | SQL inside the warehouse after loading (ELT), usually with dbt |
| Processing | Teradata, SAP BW or Oracle on fixed hardware | Snowflake, BigQuery, Amazon Redshift or Databricks, billed for use |
| Analytics and BI | Scheduled reports and OLAP cubes | Tableau, Power BI, Looker, a semantic layer and reverse ETL |
| Automation | Months of planned, staged transformation projects | Schema-drift handling, dbt tests, orchestration and data observability |
The Future of EDW
In the future, we will say “enterprise data warehouse” but mean much more. The original vision of the EDW was to be a core organizational infrastructure managing data for business analysis and visibility. Today, an entire stack of big data tools serves this exact purpose, but in ways the original data warehouse architects never imagined.
Two shifts are already visible. Open table formats already separate data from the engine: the same Iceberg tables in object storage can be queried by Snowflake, BigQuery, Redshift or Databricks, letting a company change engines without moving its data. Warehouses also now run AI functions over text and answer questions written in plain language. This brings more of the analytics layer directly to the data, rather than requiring a separate tool for every kind of analysis.
In 2030 and beyond, say goodbye to the EDW as an organizational system someone bought and installed. And start thinking of EDW as an ecosystem of tools that help you go from data to insights.
Common questions
What is an enterprise data warehouse (EDW)?
An enterprise data warehouse is a central store of historical data from sales, finance, ERP and other business systems. It is organized for reporting, dashboards and BI analysis rather than daily transactions. It integrates data from many sources so the whole company works from the same numbers.
Is the modern data stack the same as an EDW?
The modern data stack does the same job as an EDW, but with different parts. Instead of one product, separate tools handle storage, ingestion, transformation, processing and analytics. The cloud warehouse at its center plays the role the EDW used to play, supported by the other layers.
Is Hadoop still used for data warehousing?
Hadoop is still an Apache project and runs in some on-premises clusters, but new analytics platforms rarely start on it. Cloud object storage with open table formats has largely taken over HDFS’s storage role in new stacks, while cloud warehouses or Spark-based lakehouses handle the processing.
What is data warehouse automation?
Data warehouse automation is tooling that removes manual pipeline work. Managed connectors load and update sources, while transformation frameworks such as dbt provide automated tests. Schedulers run jobs in order, and monitoring flags stale or broken tables so the team can investigate failures.
Does a small company need an EDW?
A small company does not need an EDW in the old sense of a large installed system. A small team can start with one cloud warehouse, a managed connector and a BI tool, paying for usage, then add transformation, orchestration and monitoring as sources and users grow.
Where to next
Data Warehouse Architecture: Traditional vs. Cloud explains the processing layer, while Data Warehouse vs. Data Lake covers storage. For the integration layer, 3 Ways to Build an ETL Process explains process options, and the ETL tools overview covers tools that move data between systems. Data Warehouses compares the main cloud platforms that can sit at the center of your stack.
Snowflake, BigQuery, Redshift, Databricks, Fivetran, Airbyte and the rest, with pricing and what each one replaces.
Browse the tools