Quick answer:
The core Redshift ETL pattern is still to stage files in Amazon S3, bulk load them with COPY, transform the data in staging tables and upsert into target tables with MERGE. MERGE has been generally available since April 2023.
AWS Glue runs managed Spark jobs at $0.44 per DPU-hour, billed per second with a 1-minute minimum. Third-party tools such as Fivetran, Airbyte and Stitch add ready-made connectors. For supported sources, zero-ETL integrations, auto-copy from S3 and streaming ingestion from Kinesis or Amazon MSK load data without pipeline code.
It’s easier than ever to load data into the Amazon Redshift data warehouse. There are four primary ways to extract data from a source and load it into a Redshift data warehouse:
- Build your own ETL workflow
- Use Amazon’s managed ETL service, Glue
- Use one of several third-party cloud ETL services that work with Redshift
- Use Redshift’s native loading features: zero-ETL integrations, auto-copy from S3 and streaming ingestion
In this post you’ll learn how AWS Redshift ETL works and the best method to use for your use case.
What is ETL?
Extract-Transform-Load (ETL) is the process of pulling structured data from data sources like OLTP databases or flat files, cleaning and organizing the data to facilitate analysis, and loading it to a data warehouse.
On Redshift today, many teams flip the order to ELT: load raw data into Redshift first, then clean and model it with SQL inside the warehouse. dbt has a Redshift adapter for this transformation work. The methods below support both orders; the difference is where the transformation runs.
What is Amazon Redshift?
Redshift is a petabyte-scale, managed data warehouse from Amazon Web Services. You can easily build a cluster of machines to store data and run very fast relational queries, or use Redshift Serverless and let AWS manage capacity for you. Start small and scale up indefinitely by adding more machines or more Redshift clusters (for higher concurrency). The Redshift architecture chapter explains how the pieces fit together.
1. Build your own Redshift ETL Pipeline
Amazon recommends you design your ETL process around Redshift’s unique architecture, to leverage its performance and scalability.
Follow these best practices to design an efficient ETL pipeline for Amazon Redshift:
- COPY from multiple files of the same size: Redshift uses a Massively Parallel Processing (MPP) architecture (like Hadoop). Workloads are broken up and distributed to multiple “slices” within compute nodes, which run tasks in parallel. Redshift now splits uncompressed CSV files and Parquet or ORC files of 128 MB or more on its own. For files it can’t split, such as JSON or GZIP-compressed CSV, ensure each slice gets the same amount of work by splitting data into equal-sized files, between 1 MB and 1 GB after compression, in a number that is a multiple of the slices in your cluster.
- Bulk load data from S3: retrieve data from data sources and stage it in S3 before loading to Redshift. Use Amazon manifest files to list the files to load to Redshift from S3, avoiding duplication. Use temporary staging tables to hold data for transformation, and run the
ALTER TABLE APPENDcommand to swap data from staging tables to target tables. This is faster thanCREATE TABLE ASorINSERT INTO. - Multiple steps in a single transaction: commits to Amazon Redshift are expensive. If you have multiple transformations, don’t commit to Redshift after every one. Run multiple SQL queries to transform the data, and only when in its final form, commit it to Redshift. Below is an example provided by Amazon:
Begin
CREATE temporary staging_table;
INSERT INTO staging_table SELECT .. FROM source (transformation logic);
DELETE FROM daily_table WHERE dataset_date =?;
INSERT INTO daily_table SELECT .. FROM staging_table (daily aggregate);
DELETE FROM weekly_table WHERE weekending_date=?;
INSERT INTO weekly_table SELECT .. FROM staging_table(weekly aggregate);
Commit
ALTER TABLE APPEND commits immediately and can’t run inside a BEGIN…END transaction block. Run it separately after the transformation transaction commits.
- Perform table maintenance regularly: Redshift is a columnar database, and it now sorts tables, runs
VACUUM DELETEand runsANALYZEautomatically in the background.COPYalso analyzes a table automatically when it loads into an empty one. After very large loads or deletes, you can still run theVACUUMoperation to re-sort tables and remove deleted blocks, and theANALYZEoperation to update statistics metadata, which helps the Redshift Query Optimizer generate accurate query plans. The Analyze & Vacuum Utility helps you schedule this automatically. - Use workload management: Redshift is optimized primarily for read queries. To avoid commit-heavy processes like ETL running slowly, use Redshift’s Workload Management engine (WLM). Automatic WLM, the default on the default parameter group and the mode AWS recommends, manages memory and concurrency for you, and you can still route ETL to its own queue. If you run manual WLM, define a separate workload queue for ETL runtime. Configure it to run with 5 or fewer slots, claim extra memory available in a queue, and take advantage of dynamic memory parameters.
- Use
UNLOADto extract large result sets: in Redshift, fetching a large number of rows usingSELECTstalls the cluster leader node, and thus the entire cluster. Instead, use theUNLOADcommand to extract large result sets directly to S3, writing data in parallel to multiple files in CSV, Parquet or JSON format, without stalling the leader node. - Use
MERGEfor upserts: Generally available since April 2023,MERGEupdates matching rows and inserts new ones from a staging table in one statement. AWS documentation leads with MERGE, while retaining delete-and-insert as an alternative. A simplified REMOVE DUPLICATES mode is also available.
MERGE INTO sales
USING sales_staging
ON sales.sale_id = sales_staging.sale_id
WHEN MATCHED THEN UPDATE SET amount = sales_staging.amount, updated_at = sales_staging.updated_at
WHEN NOT MATCHED THEN INSERT VALUES (sales_staging.sale_id, sales_staging.amount, sales_staging.updated_at);- Use Amazon Redshift Spectrum for ad hoc processing: for ad hoc analysis on data outside your regular ETL process (for example, data from a one-time marketing promotion) you can query data directly from S3. Amazon Redshift Spectrum can run ad-hoc relational queries on big data in the S3 data lake, without ETL. On the Graviton-based RG nodes AWS launched in May 2026, a built-in data lake query engine runs these queries on the cluster itself, with no per-TB scan charge.
- Monitor daily ETL health using diagnostic queries: use the monitoring scripts provided by Amazon and system views such as
SYS_LOAD_HISTORYandSYS_QUERY_HISTORYto monitor ETL performance, and resolve problems early before they impact data loading capacity.
For more details on these best practices, see the Top 9 best practices post on the AWS Big Data blog, last updated in 2024.
2. Redshift with AWS Glue
Amazon Web Services offers a managed ETL service called Glue, based on a serverless architecture, which you can leverage instead of building an ETL pipeline on your own.
The advantage of AWS Glue vs. setting up your own AWS data pipeline, is that Glue automatically discovers data model and schema, and even auto-generates ETL scripts. However, it comes at a price: Amazon charges $0.44 per Data Processing Unit (DPU) hour for Spark ETL jobs, billed per second with a 1-minute minimum (a job uses at least 2 DPUs and 10 by default), and charges separately for its data catalog and data crawler.
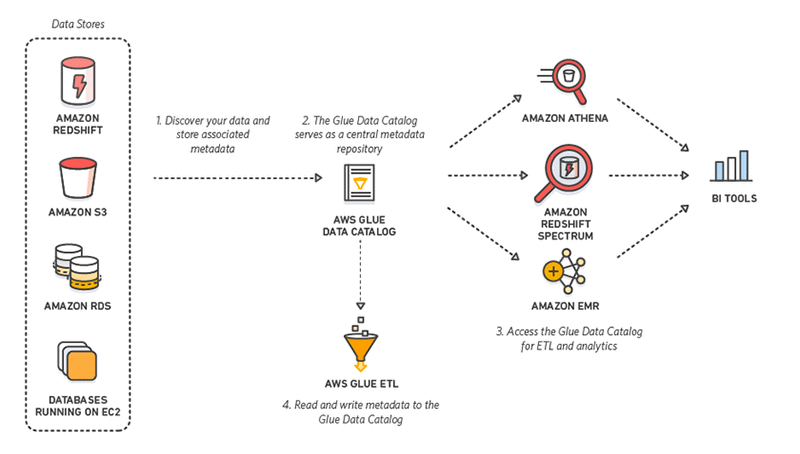
AWS Glue offers the following capabilities:
- Integrated Data Catalog: a persistent metadata store that stores table definitions, job definitions, and other control information to help you manage the ETL process. Glue automatically creates partitions to make queries more efficient.
- Automatic schema discovery: Glue crawlers connect to your data, runs through a list of classifiers to determine the best schema for your data, and creates the appropriate metadata in the Data Catalog.
- Code generation: Glue automatically generates Scala or Python code, written for Apache Spark, to extract, transform, flatten, enrich, and load your data. In Glue Studio you can build a job visually and then edit the generated script.
- Notebooks and interactive sessions: Glue Studio notebooks and interactive sessions let you edit and test the auto-generated ETL scripts. Add custom readers, writers, or transformations as custom libraries. They replace developer endpoints, which only worked with Glue versions before 2.0.
- Job scheduler: Glue runs ETL jobs in parallel, either on a pre-scheduled basis, on-demand, or triggered by an event. It lets you define dependencies to build complex ETL processes. Logs are pushed to CloudWatch.
AWS Glue Flex jobs suit work that can wait, at $0.29 per DPU-hour in AWS’s pricing example. The Data Catalog stores the first million objects free each month, then charges $1 per 100,000 objects. Glue 6.0, with Spark 4.1.1, is the newest version, while new jobs default to Glue 5.1. Glue 0.9, 1.0 and 2.0 reached end of life on April 1, 2026.
3. Third-Party Redshift ETL Tools
You can leverage several lightweight, cloud ETL tools that are pre-integrated with Amazon Redshift. The main advantages of these services is that they come pre-integrated with dozens of external data sources, whereas Glue is built around Amazon infrastructure and has a shorter list of application connectors.
If all your data is on Amazon, Glue will probably be the best choice. Run a simulation first to compare costs, as they will vary depending on use case.
Stitch to Redshift
Stitch, now sold as a Qlik product, lets you select from multiple data sources, connect to Redshift, and load data to it. Stitch provides detailed documentation on how data loading behaves depending on the status of keys, columns and tables in Redshift. Stitch flattens nested objects and arrays into columns and subtables, and it is built for replication rather than transformation, so plan to transform the data once it is already in Redshift.
Fivetran, Airbyte and Matillion to Redshift
- Fivetran: Fully managed connectors replicate SaaS applications and databases into a Redshift destination on a schedule, with schema changes handled for you.
- Airbyte: Open-source connectors you can self-host or run in Airbyte Cloud, with an Amazon Redshift destination.
- Matillion: A data pipeline platform that supports Redshift and focuses on transforming data inside the warehouse.
Most of these tools load raw data and leave modeling to the warehouse, where dbt fits, while the ETL tools chapter compares the wider field.
4. Native Redshift Loading: Zero-ETL, Auto-Copy and Streaming
Redshift loads supported sources without custom pipeline code. These features complement the three methods above rather than replacing them.
- Zero-ETL integrations: Redshift replicates data from Aurora MySQL, Aurora PostgreSQL, Amazon RDS for MySQL, PostgreSQL and Oracle, DynamoDB, and Oracle Database@AWS. Through AWS Glue, application sources include Salesforce, SAP, ServiceNow, Zendesk, Meta ads and Instagram ads. Self-managed MySQL, PostgreSQL, SQL Server and Oracle databases are supported too.
- Auto-copy from S3: A COPY JOB, generally available since October 2024, watches an S3 prefix through an S3 event integration and loads new files automatically, using
COPY ... JOB CREATE name AUTO ON. - Streaming ingestion: Redshift reads Amazon Kinesis Data Streams or Amazon MSK topics straight into a materialized view, with no S3 staging.
- Federated queries: Redshift queries live data in RDS or Aurora PostgreSQL and MySQL in place, without copying it into warehouse tables.
Native loading suits AWS-hosted sources, but transformations still happen afterwards in SQL, so the staging, MERGE and maintenance practices from method 1 still apply where you load and update warehouse tables.
Which Redshift ETL Method Should You Choose?
Choose by source coverage, transformation needs and how much pipeline operation your team can own.
| Method | Best for | Watch out for |
|---|---|---|
| Build your own: COPY, staging, MERGE | Full control, lowest tool cost; teams comfortable with SQL and S3 | You own scheduling, monitoring and maintenance |
| AWS Glue | Data already on AWS, Spark transformations and serverless jobs | DPU-hour costs add up on long or frequent jobs |
| Third-party tools | Many SaaS sources and little engineering time | Subscription pricing grows with data volume |
| Native zero-ETL, auto-copy and streaming | Supported AWS databases, S3 drops, Kinesis or MSK streams | Limited source coverage; transformations still run afterwards |
Run a cost simulation on a sample workload before committing; costs vary by use case.
Common questions
What is the fastest way to load data into Redshift?
Bulk load staged files from S3 with one COPY command per table so all slices can work in parallel. Use a manifest to specify the intended files and avoid duplicate file entries. Avoid row-by-row INSERTs for bulk ingestion; they do not use Redshift’s parallel loading path.
Does Redshift support MERGE for upserts?
Yes. Redshift MERGE has been generally available since April 2023. A MERGE from a staging table updates matching target rows and inserts new rows in a single statement. The older delete-and-insert pattern still works, but MERGE expresses the upsert directly without separate delete and insert statements.
How much does AWS Glue cost for Redshift ETL?
AWS Glue Spark jobs cost $0.44 per DPU-hour, billed per second with a 1-minute minimum. Jobs use at least 2 DPUs and 10 by default. Flex is cheaper for jobs that can wait. Data Catalog and crawlers are billed separately, and prices vary by Region.
What is zero-ETL in Amazon Redshift?
Zero-ETL is a managed integration that replicates data from supported sources such as Aurora, RDS, DynamoDB and some SaaS applications into Redshift without a pipeline to build. It removes the custom ingestion pipeline, not the transformation work: you still clean and model the loaded data afterwards with SQL.
Where to next
For how Redshift stores and processes the data you load, read Redshift Architecture, Redshift Columnar Storage 101 and Redshift Cluster 101. For loading strategy, Data Warehouse ETL covers full versus incremental loads, and Data Warehouse Testing 101 covers checking what you loaded. Data Warehouse Architecture: Traditional vs. Cloud gives the bigger picture.
Snowflake, BigQuery, Redshift, Databricks, Fivetran, Airbyte and the rest, with pricing and what each one replaces.
Browse the tools