Quick answer:
There are three ways to decide how to build an ETL process, and they are alternatives, not stages of evolution:
- Batch ETL: extract on schedule, validate and transform with Python or SQL, stage, then MERGE into the warehouse.
- Streaming ETL: capture changes through Debezium into Kafka, transform with Flink or Kafka Streams, and deliver in seconds.
- Managed ELT: Fivetran, Airbyte or dlt load raw warehouse tables; dbt models them.
Default to batch unless you need seconds-level freshness; choose managed ELT for SaaS apps and databases with existing connectors.
What is ETL (Extract Transform Load)?
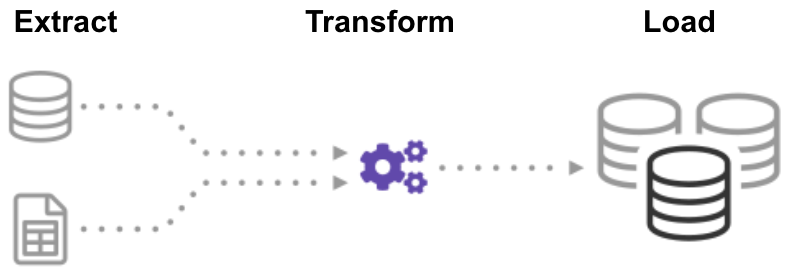
ETL (Extract, Transform, Load) is an automated process which takes raw data, extracts the information required for analysis, transforms it into a format that can serve business needs, and loads it to a data warehouse. ETL typically summarizes data to reduce its size and improve performance for specific types of analysis.
When you build an ETL infrastructure, you must first integrate data from a variety of sources. Then you must carefully plan and test to ensure you transform the data correctly. This process is complicated and time-consuming.
The methods share the ETL goal: usable source data in a warehouse. Choose by required freshness, infrastructure ownership and whether transformation runs before loading or inside the warehouse.
Let’s start by looking at how to do this the traditional way: batch processing.
1. Building an ETL Pipeline with Batch Processing
In a traditional ETL pipeline, you process data in batches from source databases to a data warehouse. It’s challenging to build an enterprise ETL workflow from scratch, so you typically rely on ETL tools, which simplify and automate much of the process.
To build an ETL pipeline with batch processing, you need to:
-
Create reference data: create a dataset that defines the set of permissible values your data may contain. For example, in a country data field, specify the list of country codes allowed.
-
Extract data from different sources: the basis for the success of subsequent ETL steps is to extract data correctly. Take data from a range of sources, such as APIs, non/relational databases, XML, JSON, CSV files, and convert it into a single format for standardized processing.
-
Validate data: Keep data that have values in the expected ranges and reject any that do not. For example, if you only want dates from the last year, reject any values older than 12 months. Analyze rejected records, on an on-going basis, to identify issues, correct the source data, and modify the extraction process to resolve the problem in future batches.
-
Transform data: Remove duplicate data (cleaning), apply business rules, check data integrity (ensure that data has not been corrupted or lost), and create aggregates as necessary. For example, if you want to analyze revenue, you can summarize the dollar amount of invoices into a daily or monthly total. You need to program numerous functions to transform the data automatically.
-
Stage data: You do not typically load transformed data directly into the target data warehouse. Instead, data first enters a staging database which makes it easier to roll back if something goes wrong. At this point, you can also generate reports for regulatory compliance, or diagnose and repair data problems.
-
Publish to your data warehouse: Load data to the target tables. Some data warehouses overwrite existing information whenever the ETL pipeline loads a new batch: this might happen daily, weekly, or monthly. In other cases, the ETL workflow can add data without overwriting, including a timestamp to indicate it is new. You must do this carefully to prevent the data warehouse from “exploding” due to disk space and performance limitations.
Batch Tools in 2026
- Extract and load: Fivetran provides managed connectors; Airbyte offers self-hosted or Cloud options; dlt is a pip-installable Python library released roughly monthly.
- Orchestration: use Apache Airflow 3.x, Dagster or Prefect. Airflow 3.3.1 was released in August 2026. Prefect announced its agreement to acquire Dagster Labs on 13 July 2026, with both products to be maintained.
- Transform: use Python for validation SQL handles poorly, then warehouse SQL for joins, deduplication and MERGE.
Example: Stage with Python, Publish with MERGE
This orders API example covers steps 5 and 6 in Snowflake. Precreate the target and STG_ORDERS staging table, with VARCHAR staging columns ORDER_ID, STATUS, AMOUNT and UPDATED_AT. Configure the named etl connection in Snowflake’s connections.toml, not the script.
import os

import pandas as pd
import requests
import snowflake.connector
from snowflake.connector.pandas_tools import write_pandas

conn = snowflake.connector.connect(connection_name="etl")
cur = conn.cursor()

cur.execute(
    "SELECT COALESCE(MAX(UPDATED_AT), '1900-01-01'::TIMESTAMP_NTZ) "
    "FROM ANALYTICS.CORE.ORDERS"
)
watermark = cur.fetchone()[0]

resp = requests.get(
    os.environ["ORDERS_API_URL"],
    params={"updated_since": watermark.isoformat()},
    timeout=30,
)
resp.raise_for_status()
df = pd.DataFrame(resp.json()["orders"])
df.columns = [c.upper() for c in df.columns]

cur.execute("TRUNCATE TABLE IF EXISTS ANALYTICS.STAGING.STG_ORDERS")
success, nchunks, nrows, _ = write_pandas(
    conn, df, "STG_ORDERS", database="ANALYTICS", schema="STAGING"
)
print(f"staged {nrows} rows in {nchunks} chunks")
write_pandas returns success, chunk and row counts. Check success before publishing; the target’s maximum UPDATED_AT remains unchanged until publishing succeeds.
MERGE INTO ANALYTICS.CORE.ORDERS AS t
USING (
    SELECT ORDER_ID::NUMBER AS ORDER_ID,
           STATUS,
           AMOUNT::NUMBER(12, 2) AS AMOUNT,
           UPDATED_AT::TIMESTAMP_NTZ AS UPDATED_AT
    FROM ANALYTICS.STAGING.STG_ORDERS
    QUALIFY ROW_NUMBER() OVER (PARTITION BY ORDER_ID ORDER BY UPDATED_AT DESC) = 1
) AS s
ON t.ORDER_ID = s.ORDER_ID
WHEN MATCHED AND s.UPDATED_AT > t.UPDATED_AT THEN
    UPDATE SET t.STATUS = s.STATUS, t.AMOUNT = s.AMOUNT, t.UPDATED_AT = s.UPDATED_AT
WHEN NOT MATCHED THEN
    INSERT (ORDER_ID, STATUS, AMOUNT, UPDATED_AT)
VALUES (s.ORDER_ID, s.STATUS, s.AMOUNT, s.UPDATED_AT);- Dedupe before the MERGE: QUALIFY keeps the newest row per ORDER_ID. Snowflake errors by default when source matches produce conflicting updates.
- Cast in the MERGE, not in staging: inspect bad values in STG_ORDERS before publishing to the typed target.
- Make publishing idempotent: the key match and
s.UPDATED_AT > t.UPDATED_ATguard leave the same result when you repeat the same input. - Watermarks miss hard deletes: use CDC or periodic full comparisons when source deletions matter.
Add a loop if the API pages its results. See the Snowflake MERGE reference and Data Warehouse ETL chapter for incremental loading.
2. Building an ETL Pipeline with Stream Processing
Modern data processes often include real-time data, such as web analytics data from a large e-commerce website. In these cases, you cannot extract and transform data in large batches but instead, need to perform ETL on data streams. Thus, as client applications write data to the data source, you need to clean and transform it while it’s in transit to the target data store.
Streaming ETL today usually pairs a broker with a stream processor. The broker is Apache Kafka 4.x (4.4.0 was released in October 2026) or a Kafka-compatible alternative. The processor is Apache Flink (2.3.0, June 2026) or Kafka Streams, with Spark Structured Streaming as the micro-batch option. The diagram below illustrates an ETL pipeline based on Kafka, described by Confluent:
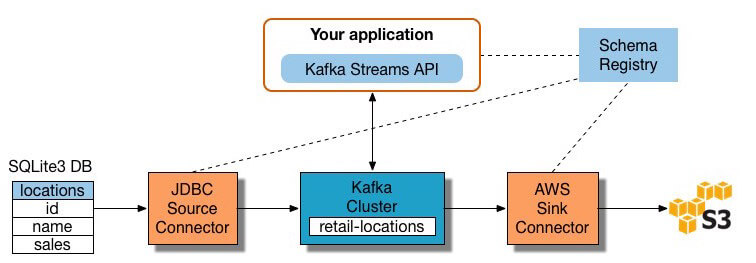
Diagram: Confluent
To build a stream processing ETL pipeline with Kafka, you need to:
-
Extract data into Kafka: a Kafka Connect source connector writes each source row or change as a key/value pair into a Kafka topic (a feed where records are stored and published). For databases, Debezium reads the transaction log and emits every insert, update and delete as an ordered change data capture event. When log access is not available, the JDBC source connector in timestamp+incrementing mode polls the table instead. Applications interested in the state of this table read from this topic. As client applications add rows to the source table, Kafka automatically writes them as new messages to the Kafka topic, enabling a real-time data stream.
-
Pull data from Kafka topics: the ETL application extracts messages from the Kafka topic as Avro records, fetches the Avro schema from a schema registry, and deserializes them. Then it creates KStream objects from the messages, or, in Flink, reads the topic as a table.
-
Transform data in a stream processor: with the Kafka Streams API, the stream processor receives one record at a time, processes it, and produces one or more output records for downstream processors. These processors can transform messages one at a time, filter them based on conditions, and perform data operations on multiple messages such as aggregation. Flink does the same work on its own cluster, and Flink SQL lets you declare a topic as a table and transform it with SQL.
-
Load data to other systems: the ETL application still holds the enriched data, and now needs to stream it into target systems, such as a data warehouse or data lake. In Confluent’s example, they propose using their S3 Sink Connector to stream the data to Amazon S3. The common sinks in 2026:
- S3 or Apache Iceberg: use an S3 sink for files; Flink or the Iceberg Kafka Connect sink for Iceberg upserts.
- Snowflake: Kafka connector v4, built on Snowpipe Streaming, documents 5 to 10 seconds end to end and supports key-pair authentication only.
- BigQuery: use the Kafka Connect sink with Storage Write API enabled (
useStorageWriteApi=true). - Redshift: use Amazon Data Firehose, renamed from Kinesis Data Firehose on 9 February 2024.
Example: Read a Kafka Topic with Flink SQL
Flink SQL declares a topic as a table. This documentation example is adapted for JSON messages:
CREATE TABLE KafkaTable (
  `user_id` BIGINT,
  `item_id` BIGINT,
  `behavior` STRING,
  `ts` TIMESTAMP_LTZ(3) METADATA FROM 'timestamp'
) WITH (
  'connector' = 'kafka',
  'topic' = 'user_behavior',
  'properties.bootstrap.servers' = 'localhost:9092',
  'properties.group.id' = 'testGroup',
  'scan.startup.mode' = 'earliest-offset',
  'format' = 'json'
);
The ts column reads the Kafka record timestamp. Choose a Flink release supported by the separately released Kafka connector; do not assume the latest Flink release is supported. For Kafka-to-Kafka Java services, stream.filter((key, value) -> value > 0) drops non-positive values before stream.to(TOPIC) writes results.
Brokers and Operations
Kafka-compatible alternatives include:
- Redpanda: a single binary under the Business Source License.
- WarpStream: stateless agents writing to object storage; acquired by Confluent in September 2024. Confluent became part of IBM on 17 March 2026.
- AutoMQ: Apache 2.0, with S3-backed storage.
Assign an owner to streaming operations:
- Register schemas and enforce compatibility.
- Route bad messages to a dead letter queue with depth alerts.
- Monitor consumer lag.
If nobody owns these operations, choose scheduled batch processing instead.
Now you know how to perform ETL processes the traditional way and for streaming data. The third way changes the order of the steps: Extract Load Transform.
What is ELT (Extract Load Transform)?
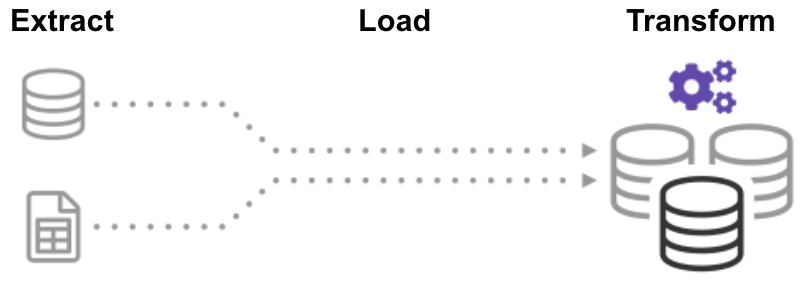
In the Extract Load Transform (ELT) process, you first extract the data, and then you immediately move it into a centralized data repository. After that, data is transformed as needed for downstream use. This method gets data in front of analysts much faster than ETL while simultaneously simplifying the architecture.
Moreover, today’s cloud data warehouse and data lake infrastructure support ample storage and scalable computing power. Thus, it’s no longer necessary to prevent the data warehouse from “exploding” by keeping data small and summarized through transformations before loading. It’s possible to maintain massive data pools in the cloud at a low cost while leveraging ELT tools to speed up and simplify data processing.
ELT loads raw personal data unless you mask it in flight, and transformations consume paid warehouse compute. Method 3 uses dbt to manage those transformations.
3. Building an ELT Pipeline with Managed Connectors and dbt
This ETL pipeline loads raw tables before dbt transforms them. Fivetran and dbt Labs completed their all-stock merger on 1 June 2026, operating as Fivetran + dbt Labs. The dbt Fusion runtime is being open sourced as dbt Core v2.0 (alpha) under Apache 2.0.
-
Connect your sources: Fivetran bills per monthly active row; Airbyte Cloud uses credits, with free self-hosting available; dlt is a Python library you run yourself.
-
Land raw tables in the warehouse: create a source-specific schema in Snowflake, BigQuery, Amazon Redshift or Databricks. Keep transformations separate so models can be rebuilt.
-
Model the data with dbt: write SQL models in dbt to turn raw tables into clean ones. Make large fact tables incremental.
-
Test and schedule: add unique, not_null and relationships tests to dashboard models. For example, run
dbt buildhourly after ingestion in dbt Cloud, Airflow or Dagster, with source freshness alerts. -
Connect your BI tool: point reports at the modeled schema, not the raw one.
This dbt documentation example reprocesses days at or after the newest stored date; unique_key replaces existing days rather than appending duplicates.
{{
    config(
        materialized='incremental',
        unique_key='date_day'
    )
}}

select
    date_trunc('day', event_at) as date_day,
    count(distinct user_id) as daily_active_users
from {{ ref('app_data_events') }}

{% if is_incremental() %}
where date_day >= (select coalesce(max(date_day), '1900-01-01') from {{ this }})
{% endif %}

group by 1
For dbt incremental models, is_incremental() is false on the first run or with --full-refresh, so this file also rebuilds the table.
What Managed ELT Costs (November 2026)
Estimate connector usage and warehouse compute separately; confirm these November 2026 prices before purchase.
| Tool | Billing unit | Free option | Paid anchor |
|---|---|---|---|
| Fivetran | Monthly active rows (MAR) per connection | Free plan | $5 base charge per connection with 1 to 1M MAR monthly; Free plan exempt |
| Airbyte | Credits (Standard), Data Workers (Pro) | Free self-hosted version | Standard roughly $10 to $20 monthly plus usage credits, per third-party listings |
| dlt | None for library | Open source | Your compute and engineering time |
| dbt | Cloud developer seats and model runs | dbt Core, Apache 2.0; one-seat Cloud Developer plan per third-party pricing guides | Cloud Starter about $100 per developer seat monthly, per third-party pricing guides |
Fivetran’s pricing docs count each distinct primary key once per calendar month, regardless of update frequency. Inserts, updates and deletes count toward MAR, as do destination deletes followed by re-syncs. Estimate distinct active rows, not the number of update events.
When Self-Hosting Beats the Bill
Self-hosted Airbyte or dlt removes license fees, not maintenance. One 2026 comparison estimates $600 to $3,000 monthly engineering labor at $150 an hour for upgrades, connector fixes and monitoring.
As a rule of thumb, with fewer than two data engineers, buy connectors. Self-host only with a named owner and savings after labor; model managed costs at 3x and 10x current volume.
Which of the Three Should You Build?
Choose batch, streaming or managed ELT by freshness, source coverage and the operations your team can own.
| Criterion | 1. Batch ETL | 2. Streaming ETL | 3. Managed ELT |
|---|---|---|---|
| Latency | Scheduled, often hourly or daily | Seconds; Snowflake connector documents 5 to 10 seconds | Connector sync schedule |
| Typical sources | Files, custom APIs, legacy systems | Database CDC and application events | SaaS apps and databases |
| Team | Python, SQL and orchestration owner | Broker and processor operators, or managed-service budget | SQL analysts plus ingestion ownership |
| Main cost driver | Job hosting and warehouse compute | Always-on brokers and processors | Connector usage plus warehouse compute |
| Typical failure | Duplicate rows on reruns | Schema changes breaking consumers | Unexpected usage bills or untested models |
Pick batch ETL if hourly or daily freshness is enough, sources are custom or file based, or data needs masking before loading. Start here unless latency requirements justify continuously running brokers and processors.
Pick streaming ETL if an action depends on seconds-old data, such as a fraud check, and someone owns the brokers. Budget for schema compatibility and consumer lag monitoring, not just throughput.
Pick managed ELT if SaaS apps and databases dominate, analysts write SQL transformations, and connector fees cost less than the engineering time they replace. Compare usage growth with the labor required to self-host.
Combine methods when needed: mask personal data in an ETL step and load other sources through managed ELT. Warehouse query-time masking is not a substitute when raw values must never land: it hides values from selected readers but keeps them stored.
Common Mistakes When Building an ETL Process
Test reruns and upstream schema changes before treating a successful first load as production-ready.
- Blind INSERTs in batch loads: reruns duplicate rows and inflate metrics. MERGE on a stable business key, as in method 1, and test by running the job twice.
- Trusting a watermark to catch deletes: updated_since queries miss hard deletes and can miss updates when clocks drift. Use log-based CDC or a periodic full comparison.
- Reading only the first page of an API: the job succeeds with partial data. Loop until the API stops returning a next-page token.
- Streaming without a schema registry: renamed fields can break older consumers. Register schemas and enforce compatibility before producers deploy, rather than discovering mismatches in production.
- Ignoring how MAR is counted: source deletes and destination re-syncs count toward Fivetran MAR. Backfills or table rebuilds can raise bills; check usage after large changes.
- Shipping dbt models without tests: a broken join reaches the dashboard first. Add unique and not_null tests on the key of every model a report reads, alongside relationship tests where applicable.
Common questions
What is the difference between ETL and ELT?
ETL transforms data before loading it; ELT loads raw data first and transforms it inside the warehouse, usually with dbt SQL models. Choose ETL for pre-load masking or non-SQL transformations. Methods 1 and 3 show how the order changes the pipeline.
Should I build a batch or a streaming pipeline first?
Start with batch unless a decision depends on seconds-old data. Scheduled batch jobs are easier to rerun and debug; streaming adds always-on brokers and processors. Spark Structured Streaming’s default micro-batch engine processes small batches continuously, with roughly 100 ms latency at best, rather than waiting for an hourly schedule.
Should I use Kafka Streams or Flink?
Choose Kafka Streams for Kafka-to-Kafka processing embedded in a Java service; choose Flink for multi-source pipelines. Kafka Streams is a library with little additional infrastructure. Flink runs its own cluster, supports batch and streaming, and offers Flink SQL. Its broader connector coverage adds cluster-operating responsibility.
Is dbt still free after the Fivetran merger?
Yes. dbt Core remains free under Apache 2.0, and the Fusion runtime is being released as dbt Core v2.0 (alpha) under that license. Third-party pricing guides list a free one-seat dbt Cloud Developer plan and paid seats around $100 monthly. The merger closed on 1 June 2026.
Where to next
Compare connectors in ETL Tools 2026, then follow the ETL Tutorial for Python and SQL with a history table. Full vs Incremental Loading covers watermarks and when to reload everything. The next chapter, Redshift ETL, applies these methods to Amazon Redshift.
Snowflake, BigQuery, Redshift, Databricks, Fivetran, Airbyte and the rest, with pricing and what each one replaces.
Browse the tools