Quick answer:
The difference between a data warehouse and a database is the workload each serves. A database (OLTP) records an application’s current transactions, typically in normalized, row-oriented tables built for many small reads and writes. A data warehouse (OLAP) integrates historical data from many sources, usually in denormalized, columnar tables built for complex analytical queries.
The old gaps have narrowed. Snowflake, BigQuery and Redshift document ACID transactions, scale concurrency by adding compute and can load streams within seconds. Most businesses still run both: the database handles application transactions, while the warehouse supports analysis. ETL, ELT or change data capture moves data between them.
Does your business deal with a lot of transactions each day? Do you have years of historical data you want to analyze to improve your business? Great! Then you need a database and a data warehouse… but which data goes where?
Databases and data warehouses are both systems that store data. But they serve very different purposes. In this article, we’ll explain what they do, the key differences between them, and why using them effectively is essential for you to grow your business.
We’ll start with some high-level definitions before giving you more detailed explanations.
What is a Database?
A database stores real-time information about one particular part of your business: its main job is to process the daily transactions that your company makes, e.g., recording which items have sold. Databases handle a massive volume of simple queries very quickly.
Common examples include PostgreSQL, MySQL, Microsoft SQL Server and Oracle, often run through managed services such as Amazon RDS, Amazon Aurora or Azure SQL Database. These transactional engines typically store data row by row, which suits reading or writing a complete record, such as an order or booking. Their transactions follow the ACID model to keep changes reliable.
What is a Data Warehouse?
A data warehouse is a system that pulls together data from many different sources within an organization for reporting and analysis. The reports created from complex queries within a data warehouse are used to make business decisions.
A data warehouse stores historical data about your business so that you can analyze and extract insights from it. Traditionally it was loaded in batches, often overnight, so it did not hold the very latest transactions. Modern cloud warehouses can also take in streaming data within seconds, but their main job is still analysis across history, not running the business day to day.
Today most new warehouses run in the cloud, and Snowflake, BigQuery, Amazon Redshift and Databricks SQL warehouses separate storage from compute, so you pay for the processing your queries use. You can compare them in our overview of data warehouses.
Data Warehouse vs. Database
Let’s dive into the main differences between data warehouses and databases.
Processing Types: OLAP vs OLTP
The most significant difference between databases and data warehouses is how they process data.
Databases use OnLine Transactional Processing (OLTP) to delete, insert, replace, and update large numbers of short online transactions quickly. This type of processing immediately responds to user requests, and so is used to process the day-to-day operations of a business in real-time. For example, if a user wants to reserve a hotel room using an online booking form, the process is executed with OLTP.
Data warehouses use OnLine Analytical Processing (OLAP) to analyze massive volumes of data rapidly. This process gives analysts the power to look at your data from different points of view. For example, even though your database records sales data for every minute of every day, you may just want to know the total amount sold each day. To do this, you need to collect and sum the sales data together for each day. OLAP is specifically designed to do this, so these summaries run far faster on a data warehouse than the same calculation would on an OLTP system.
Optimization
A database is optimized to update (add, modify, or delete) data with maximum speed and efficiency. Response times from databases need to be extremely quick for efficient transaction processing. The most important aspect of a database is that it records the write operation in the system; a company won’t be in business very long if its database didn’t make a record of every purchase!
Data warehouses are optimized to rapidly execute a low number of complex queries on large multi-dimensional datasets.
Data Structure
The data in databases are normalized. The goal of normalization is to reduce and even eliminate data redundancy, i.e., storing the same piece of data more than once. This reduction of duplicate data leads to increased consistency and, thus, more accurate data as the database stores it in only one place.
Normalizing data splits it into many different tables. Each table represents a separate entity of the data. For example, a database recording BOOK SALES may have three tables to denote BOOK information, the SUBJECT covered in the book, and the PUBLISHER.
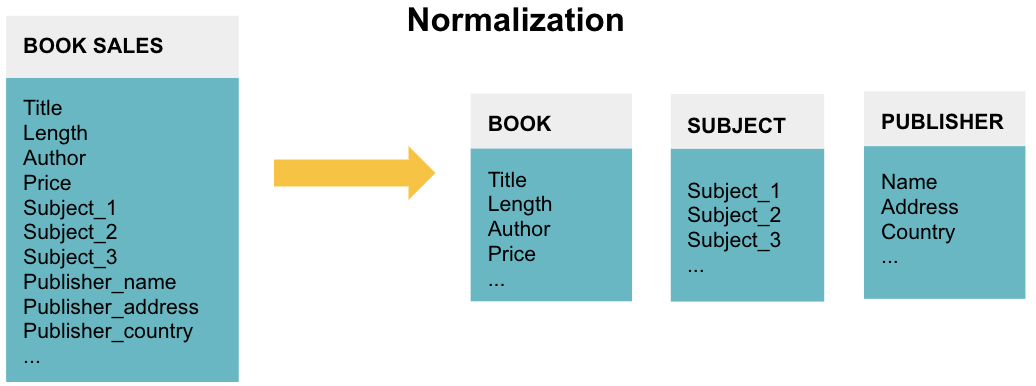
Normalizing data ensures the database takes up minimal disk space and so it is memory efficient. However, it is not query efficient. Querying a normalized database can be slow and cumbersome. Since businesses want to perform complex queries on the data in their data warehouse, that data is often denormalized and contains repeated data for easier access.
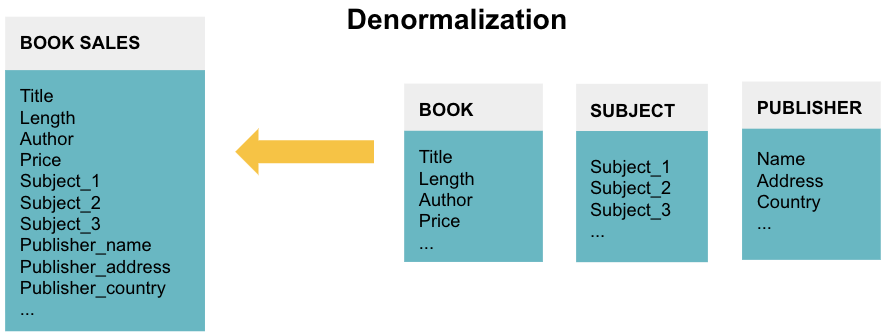
Most warehouses organize this denormalized data as a star schema: a central fact table of events, such as book sales, joined to dimension tables for books, subjects and publishers. Microsoft’s Fabric warehouse documentation calls the star schema the recommended design for analytic workloads, following Ralph Kimball’s dimensional modeling.
Storage Format: Rows vs. Columns
Transactional databases such as PostgreSQL and MySQL store each row together, which suits reading or updating one complete record. AWS’s Redshift documentation describes row-wise storage as optimal for OLTP databases.
Warehouses store columns separately: Redshift uses columnar storage, BigQuery uses Capacitor, and Snowflake stores columns independently within micro-partitions. In Redshift’s example, reading 5 of 100 columns touches about 5% of the data; similar values within a column compress well. Redshift Columnar Storage 101 explains the mechanics.
Data Analysis
Databases usually just process transactions, but it is also possible to perform data analysis with them. However, in-depth exploration is challenging for both the user and computer due to the normalized data structure and the large number of table joins you need to perform. It requires a skilled developer or analyst to create and execute complex queries on a DataBase Management System (DBMS), which takes up a lot of time and computing resources. Moreover, the analysis does not go deep: the best you can get is a one-time static report as databases just give a snapshot of data at a specific time.
Data warehouses are designed to perform complex analytical queries on large multi-dimensional datasets in a straightforward manner. There is no need to learn advanced theory or how to use sophisticated DBMS software. Not only is the analysis simpler to perform, but the results are much more useful; you can dive deep and see how your data changes over time, rather than the snapshot that databases provide.
Data Timeline
Databases process the day-to-day transactions for one aspect of the business. Therefore, they typically contain current, rather than historical data about one business process.
Data warehouses are used for analytical purposes and business reporting. Data warehouses typically store historical data by integrating copies of transaction data from disparate sources. Data warehouses can also use real-time data feeds for reports that use the most current, integrated information.
Near-real-time loading is now standard: Snowpipe Streaming makes rows queryable in as little as 5 seconds. Data written through the BigQuery Storage Write API is readable immediately. Redshift streaming ingestion reads Kinesis Data Streams or Amazon MSK into materialized views without staging files in S3.
Concurrent Users
Databases support thousands of concurrent users because they are updated in real-time to reflect the business’s transactions. Thus, many users need to interact with the database simultaneously without affecting its performance.
However, only one user can modify a piece of data at a time: it would be disastrous if two users overwrote the same information in different ways at the same time!
Data warehouses traditionally supported a limited number of concurrent users. A data warehouse is separated from front-end applications, and using it involves writing and executing complex queries. These queries are computationally expensive, so on a fixed, on-premises system only a small number of people could use it simultaneously.
Cloud warehouses add compute on demand instead. Snowflake’s Enterprise Edition multi-cluster warehouses start extra clusters as queries queue. Redshift Concurrency Scaling automatically adds capacity for thousands of concurrent users and concurrent queries, while BigQuery on-demand projects get up to 2,000 concurrent slots. Concurrency is now mostly a question of cost and configuration.
ACID Compliance
Database transactions usually are executed in an ACID (Atomic, Consistent, Isolated, and Durable) compliant manner. This compliance ensures that data changes in a reliable and high-integrity way. Therefore, it can be trusted even in the event of errors or power failures. Since the database is a record of business transactions, it must record each one with the utmost integrity.
Since data warehouses focus on reading, rather than modifying, historical data from many different sources, ACID compliance was historically less strictly enforced. Today the major cloud warehouses document ACID transactions: Snowflake states that its transactions guarantee ACID properties, BigQuery multi-statement transactions keep strict ACID properties with snapshot isolation, and Redshift runs concurrent writes under snapshot or serializable isolation.
Open table formats such as Delta Lake and Apache Iceberg bring the same transactional guarantees to files in a data lake, which is what makes a lakehouse possible.
Database vs. Data Warehouse SLAs
Database SLAs are strict because any system failure could result in lost revenue and lawsuits. The published figures depend on how the database is deployed: Amazon RDS offers service credits below 99.95% monthly uptime for Multi-AZ instances and below 99.5% for Single-AZ instances, while Amazon Aurora’s commitment reaches 99.99% for Multi-AZ clusters.
SLAs for some really large on-premises data warehouses used to have downtime built in to accommodate periodic uploads of new data. Modern cloud warehouses load data while queries keep running, and they publish uptime figures close to those of databases: Amazon Redshift commits to 99.99% for Multi-AZ clusters and 99.9% for Single-AZ multi-node clusters and Redshift Serverless, and Google raised the BigQuery SLA to 99.99% in 2020.
Database Use Cases
Databases process the day-to-day transactions in an organization. Some examples of database applications include:
- An e-commerce website creating an order for a product it has sold
- An airline using an online booking system
- A hospital registering a patient
- A bank adding an ATM withdrawal transaction to an account
Data Warehouse Use Cases
Data warehouses provide high-level reporting and analysis that empower businesses to make more informed business decisions. Use cases include:
- Segmenting customers into different groups based on their past purchases to provide them with more tailored content
- Predicting customer churn using the last ten years of sales data
- Creating demand and sales forecasts to decide which areas to focus on next quarter
- Feeding dashboards in BI tools with consistent, company-wide metrics, as covered in BI and data warehousing
Database vs. Data Warehouse Comparison
| Property | Database | Data Warehouse |
|---|---|---|
| Processing Method | OnLine Transaction Processing (OLTP) | OnLine Analytical Processing (OLAP) |
| Optimization | Deletes, inserts, replaces and updates large numbers of short online transactions quickly. | Rapidly analyze massive volumes of data and provide different viewpoints for analysts. |
| Data structure | Highly normalized data structure with many different tables containing no redundant data. Thus, data is more accurate but slow to retrieve. | Denormalized data structure, often a star schema, with few tables containing repeat data. Thus, data is potentially less accurate but fast to retrieve. |
| Storage format | Row-oriented: each record is stored together | Columnar: each column is stored and compressed separately |
| Data timeline | Current, real-time data for one part of the business | Historical data for all parts of the business, loaded in batches or near real time |
| Data analysis | Analysis is slow and painful due to the large number of table joins needed and the small time frame of data available. | Analysis is fast and easy due to the small number of table joins needed and the extensive time frame of data available. |
| Concurrent users | Thousands of concurrent users supported. However, only one user can modify each piece of data at a time. | Traditionally a small number; cloud warehouses add compute to serve many more. |
| ACID compliance | Records data in an ACID-compliant manner to ensure the highest levels of integrity. | ACID transactions in Snowflake, BigQuery and Redshift; isolation levels vary. |
| Uptime | 99.5% to 99.99%, depending on the deployment | Up to 99.99% in the cloud; older on-premises systems scheduled load windows |
| Storage | Limited to a single data source from a particular business function | All data sources from all business functions |
| Query type | Simple transactional queries | Complex queries for in-depth analysis |
| Data summary | Highly granular and precise | As granular and precise as you want it to be |
Now you understand the difference between a database and a data warehouse and when to use which one. Your business needs both an effective database and data warehouse solution to truly succeed in today’s economy.
How Data Moves from a Database to a Data Warehouse
Data pipelines copy transaction data into a warehouse. The classic pattern is ETL: extract data from the source, transform it, then load it into the warehouse. ELT loads data first and transforms it inside the warehouse with SQL, often with dbt. Managed connectors such as Fivetran and Airbyte handle extraction and loading for databases and SaaS applications.
For fresher data, log-based change data capture streams inserts, updates and deletes from the transaction log, as the open-source tool Debezium does. AWS zero-ETL integrations replicate supported Aurora databases, RDS for MySQL, PostgreSQL or Oracle, and DynamoDB into Redshift without a pipeline for you to build. Our ETL tools chapter compares the options.
When Databases and Data Warehouses Overlap
The categories still matter, but several products now sit on both sides of the line.
- PostgreSQL as a small warehouse: PostgreSQL can serve as a warehouse for modest data volumes; PostgreSQL as a data warehouse covers the trade-offs. The pg_duckdb extension embeds DuckDB’s columnar engine in Postgres, while Google’s AlloyDB adds an in-memory columnar engine beside its row store.
- HTAP databases: Hybrid transactional/analytical systems run both workloads on one platform: SingleStore uses a unified storage engine, while TiDB pairs its TiKV transactional store with TiFlash column replicas. Snowflake hybrid tables add a row-based engine with row-level locking, generally available on AWS and Azure.
- Embedded analytics: DuckDB is an in-process OLAP database that runs inside an application or notebook with a columnar-vectorized engine. Analysts can query files without a separate warehouse server.
- Lakehouses: Delta Lake and Apache Iceberg tables add transactions to a data lake, so platforms such as Databricks can query lake files with warehouse-style SQL. See Data Warehouse vs. Data Lake.
Even so, most businesses keep a separate warehouse, because heavy analytical queries on the production database compete with customer transactions, and the warehouse is where data from every system comes together.
Common questions
What is the difference between OLTP and OLAP?
OLTP handles many short transactions that insert, update and delete individual records in real time. OLAP runs fewer, complex queries that aggregate large volumes of historical data. Operational databases are built for OLTP, while data warehouses are built for OLAP and reporting across business history.
Is a data warehouse a type of database?
Yes, a data warehouse is a database designed for analysis, typically with denormalized, columnar tables and data integrated from many sources. In everyday use, “database” usually means the transactional system an application writes to, while “data warehouse” means the separate system used for reporting and historical analysis.
Is Snowflake a database or a data warehouse?
Snowflake is a cloud data warehouse whose standard tables use columnar micro-partitions built for analytical queries. Inside Snowflake, you create databases and schemas to organize data. Hybrid tables add a row-based engine for some transactional work. It is not meant to replace an application’s main operational database.
Can PostgreSQL be used as a data warehouse?
Yes, PostgreSQL can serve as a data warehouse for modest volumes, handling reporting queries and star schemas. Its row-oriented storage slows scans across very large tables, which is why teams add a columnar extension such as pg_duckdb or move analytics to a cloud warehouse as data grows.
Do I need both a database and a data warehouse?
Most businesses need both once they want reporting across systems. The database keeps application transactions fast, while the warehouse combines transaction history with other sources. A small company can start by querying a read replica and add a warehouse later as its reporting needs expand.
Where to next
To see how the warehouse compares with its neighbors, read Data Mart vs. Data Warehouse and Data Warehouse vs. Data Lake. Data Warehouse Concepts: Traditional vs. Cloud covers the design ideas behind these systems. When you are ready to choose one, Data Warehouses compares the main platforms, and the Warehouse Pricing Playbook explains how they charge.
Snowflake, BigQuery, Redshift, Databricks, Fivetran, Airbyte and the rest, with pricing and what each one replaces.
Browse the tools