Quick answer:
Data warehouse testing checks that data arrives from the sources complete, correct and on time, and that every transformation follows the business rules. The classic test types are metadata, completeness, quality, transformation, regression, incremental, integration and performance testing. On cloud warehouses, most of these checks now run as automated tests in code on every change. Monitoring catches problems after go-live.
As organizations develop, migrate, or consolidate data warehouses, they must employ best practices for data warehouse testing. The success of any on-premise or cloud data warehouse solution depends on the execution of valid test cases that identify issues related to data quality. Extract, Transform, and Load (ETL) is the common process used to load data from source systems to the data warehouse. Data is extracted from the source, transformed to match the target schema, and loaded into the data warehouse.
ETL testing ensures that the transformation of data from source to warehouse is accurate. It also involves verifying data at each point between the source and destination.
This article covers the traditional ETL testing process first, then shows how the same test types are automated in a modern ELT stack, with checks alongside the transformation code.
The Importance of Data Warehouse Testing
With data driving critical business decisions, testing the data warehouse data integration process is essential. Data comes from numerous sources. The data source affects data quality, so data profiling and data cleaning must be ongoing. Source data history, business rules, or audit information may no longer be available.
Additionally, in the ETL process, data flows through a pipeline before reaching the data warehouse. You must test the entire ETL pipeline to ensure each type of data is transformed or copied as expected. Most importantly, the data warehouse is a strategic enterprise resource. Testing is required.
In many cloud stacks, transformation now runs inside the warehouse after loading, usually as SQL models. This is the ELT pattern, and tests move into the same code. Errors also travel faster: a broken join or late source can reach dashboards, reverse ETL syncs and machine learning features within hours of a load.
Understanding the ETL Testing Process
A solid understanding of data modeling provides testing teams with information to develop the right testing strategy. During the analysis phase, the testing team must learn and understand the different stages of the data warehouse implementation including but not limited to:
- Source data profiling
- Data warehouse design
- ETL development
- Data loading and transformations
ETL testing includes multiple phases, and testing should be executed throughout the lifecycle of the data warehouse implementation, not just at the end.
Preparing for ETL Testing
A data warehouse implementation must include end-to-end testing. The QA team must test initial and incremental loads for the entire ETL process beginning with identifying source data to report and portal functions. They must also test each point between extract and load, including data load from the source extract to staging, staging to transformation and once the data reaches the data warehouse, test data extraction for display and reporting.
With traditional ETL test planning, there are six phases:
- Understanding business requirements/analysis
- Creating test plans and estimating time to completion
- Designing test cases and selecting test data
- Executing tests with bug reporting and closure
- Report summary and analysis
- Test completion
ETL testing is performed in five stages:
- Identifying data sources and requirements
- Data acquisition
- Implement business logic and Dimensional Modeling
- Build and populate data
- Build Reports
Test Planning Process
The diagram shows the traditional flow from source systems through ETL into the warehouse and on to OLAP cubes, reporting and data mining.
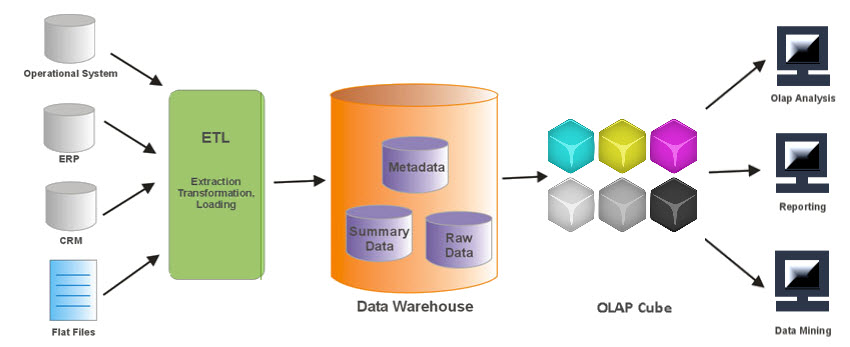
The table below maps each of the five ETL stages to the project phase in which it is built and tested.
| Identify Data Sources | Data Acquisition | Implement business logic and Dimensional Modeling | Build and populate analytical cube | Build reports |
| Requirement/Analysis | Design and Coding | Design and Coding | Design and Coding | QA and Deployment |
Test Execution Process
During execution, the testing team works through four groups of checks, from validating sources and data profiling to quality criteria and transformation rules.
| Validating required data /data sources: | Review metadata/data dictionary | Review archival/purge strategy | Test data prep |
| Data profiling: | Validate source to target mapping | Error logging, exception handling, recoverability | ETL testing (end to end) |
| Data quality and performance acceptance criteria: | Validate ETL/Data Warehouse architecture | Parallel Execution and Precedence | OLAP and cube testing |
| Data transformation rules: | Validate data model: Dimensional modeling and normalized approach | ETL pull logic: full/incremental | Report testing: drill down/drill through |
Common ETL Testing Types
Organizations use data warehouse testing to ensure that required business functions are implemented correctly. This phase includes data verification, which tests the quality of data populated into target tables. The table below describes the most common testing types.
| Test | Description |
|---|---|
| Metadata Testing | Metadata testing confirms that the table definitions conform to the data model and application design specifications. This test should include data type check, data length check, and index/constraint check. |
| Data Completeness Testing | Data Completeness testing validates that all the expected source data has been successfully loaded to the target. Tests include: Compare and Validate counts, aggregates (min, max, sum, avg), and actual data between the source and destination. |
| Data Quality Testing | Data Quality tests validate the accuracy of the data. Data profiling is used to identify data quality issues, and the ETL is designed to fix or handle these issues. Automating the data quality checks between the source and target system can help to mitigate problems post-implementation. |
| Data Transformation Testing | Data Transformation comes in two flavors: white box testing and black box testing. White box data transformation testing examines the program structure and develops test data from the program logic/code. Testers review the transformation logic from the mapping design document and the ETL code to create test cases. Black-box testing examines the functionality of an application without looking at internal structures for transformation testing; this involves reviewing the transformation logic from the mapping design document and creating the appropriate test data. |
| ETL Regression Testing | ETL Regression testing validates that the ETL produces the same output for a specific input before and after the change. |
| Incremental ETL Testing | Incremental ETL testing verifies that updates on the sources are getting loaded into the target system correctly. |
| ETL Integration Testing | ETL integration testing is end-to-end testing of the data in the ETL process and the target application. |
| ETL Performance Testing | ETL performance testing is end-to-end testing to ensure that all steps in the ETL process are working with expected data volumes. One pitfall of this testing method is the lack of actual data to emulate appropriate volumes. |
Testing mission-critical data warehouse infrastructure is required. Testing is an essential part of building a new data warehouse (or consolidating several), and it must be part of the development pipeline when the ETL process is modified or extended.
Testing data and systems systematically for inconsistencies before moving into production is necessary if the data warehouse is to be the central source of business information. Whether it is a newly built data warehouse or the consolidation of several, you must develop a thorough data warehouse testing process to help you test for, resolve, and prevent unnecessary exposure.
Automating Data Warehouse Tests in a Modern ELT Stack
The test types above have not changed, but on cloud warehouses most are now written as code. They live in version control alongside the transformation logic and run automatically on every change, rather than waiting for a separate testing phase. The table maps each classic test type to the way teams automate it today.
| Classic test type | How teams automate it today |
|---|---|
| Metadata testing | Model contracts and schema checks that fail the build when column names or data types change |
| Data completeness testing | Row-count and aggregate reconciliation between source and target after every load |
| Data quality testing | Generic tests for unique, not null, accepted values and relationships, or Great Expectations and Soda checks |
| Data transformation testing | Unit tests that run the SQL logic on mocked input rows and compare the expected output |
| ETL regression testing | Data diffs between production tables and the changed version before a merge |
| Incremental ETL testing | Source freshness checks and tests limited to the newest load window |
| ETL integration testing | A CI job that builds and tests the whole pipeline on a cloned copy of production |
| ETL performance testing | Run time and warehouse cost per job tracked against a baseline |
dbt ships four generic data tests: unique, not_null, accepted_values and relationships, declared in YAML next to each model. Each test queries for failing rows, so zero rows means a pass. Unit tests, added in dbt Core 1.8, check a model’s SQL against mocked input rows, while model contracts fail the build when column names or data types drift. The dbt build command skips downstream models when an upstream test fails.
Outside dbt, Great Expectations offers the open-source GX Core, which defines checks called Expectations in Python. Soda defines checks such as row counts, missing values, duplicates and freshness in YAML. Both run against the warehouse and can sit inside an orchestrator, where the pipeline can be configured to stop the load when a check fails.
For regression and integration testing, teams build the changed pipeline separately and compare its output with production. Snowflake CLONE, Databricks shallow clones and BigQuery table clones provide test copies without duplicating the underlying storage at creation. Datafold then compares the versions row by row, showing reviewers exactly which values a code change altered before it is merged.
Data Observability: Testing After Go-Live
Tests only catch the failures someone thought to write a test for. Data observability tools watch production tables for other problems, including late loads, sudden drops in row volume, schema changes and unusual value distributions. They use data lineage to show which reports and models sit downstream of a broken table.
Commercial options include Monte Carlo, Bigeye, Anomalo and Sifflet; Elementary is an open-source option built on dbt. Monitoring complements the test plan rather than replacing it. A monitor flags that something changed, but does not establish whether the business rule behind it is correct.
Data Warehouse Testing Best Practices
A data warehouse testing plan connects requirements to automated checks and assigns ownership when those checks fail.
- Test from the start. Tests are planned with the business requirements and run throughout implementation, rather than being added only before the warehouse goes live.
- Keep tests next to the code. Tests live in the same repository as the transformations and are reviewed in the same pull request as the changes they validate.
- Run tests on every change. A CI job builds and tests changed models on a clone or development schema, never on production tables.
- Use production-like volumes. Performance and integration tests on small samples can hide slow joins and load-window problems that appear with the expected data volumes.
- Prioritize the tables that drive decisions. Revenue, customer and finance tables get the strictest tests and alerts first.
- Make failures stop the pipeline. A failed test on a critical table blocks downstream loads and alerts a named owner instead of only writing to a log.
For the tester’s side of the job, 8 tips to becoming a great ETL tester goes deeper.
Common questions
What is the difference between ETL testing and database testing?
Database testing checks one application database, including its schema, constraints, stored procedures and transactions. ETL testing follows data across systems, from the sources through staging and transformation into the warehouse. It checks that counts, values and business rules survive each step, not just that one database works correctly.
Can data warehouse testing be automated?
Yes, most data warehouse checks can run as code. dbt tests, Great Expectations and Soda cover quality and completeness, while unit tests check transformation logic. A CI job runs these checks on every change. Business requirement reviews and report acceptance still need people to confirm that the outputs meet business needs.
What should be tested after an incremental load?
After an incremental load, testing should confirm that new and changed source rows arrived and that no rows were duplicated or dropped. The load window should match the source’s latest timestamp, and aggregates in the target should still reconcile with the source.
What is the difference between data testing and data observability?
Data tests check rules you define in advance, such as a unique key or an allowed list of values. Data observability monitors production data for unexpected changes in freshness, volume, schema or distribution. It can flag problems nobody wrote a test for, but does not replace tests of business rules.
Where to next
Data Warehouse ETL explains full and incremental loading, which shapes incremental tests, and the ETL tutorial builds a small pipeline you can practice testing on. For tool selection, ETL Tools compares the pipeline tools, while Data Warehouse Tools covers the wider stack, including testing and observability.
Snowflake, BigQuery, Redshift, Databricks, Fivetran, Airbyte and the rest, with pricing and what each one replaces.
Browse the tools