Quick answer:
Redshift architecture uses a leader node to plan queries and compute nodes, split into slices, to execute them through massively parallel processing (MPP) over compressed, columnar storage. RG and RA3 nodes use Redshift Managed Storage on Amazon S3, so compute and storage scale and bill separately.
In US East (N. Virginia), provisioned nodes cost about $0.38 to $13.04 per node-hour plus $0.024 per GB-month of managed storage. Redshift Serverless compute costs $0.375 per RPU-hour, billed per second, starting at $1.50 per hour.
Amazon Redshift is a fully-managed, analytical data warehouse service from Amazon Web Services. It can handle Petabyte-scale data, and enable analysts to query it in seconds.
The main advantage of Redshift over traditional data warehouses is that it has no upfront costs, does not require hardware setup and maintenance, and scales using Amazon’s cloud infrastructure. You can scale a provisioned Redshift cluster on demand, by adding more nodes or upgrading the node type, or use Redshift Serverless, which provisions and scales capacity automatically, to support more data or faster queries.
For more details, see our page about data warehouse architecture in this guide.
Redshift Architecture and Key Components
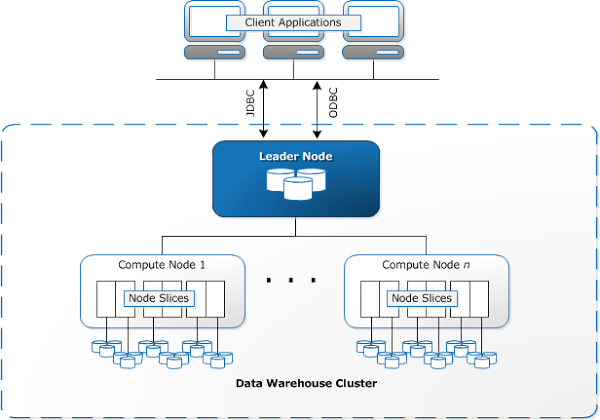
Redshift Architecture in Brief
- Redshift supports client applications, such as BI, ETL tools or external databases, and provides several ways for those clients to connect to Redshift.
- Within Redshift, users can create one or more clusters. Each cluster can host multiple databases. Most projects require only one Redshift cluster; for resilience, provisioned RG and RA3 clusters can run as a Multi-AZ deployment across two Availability Zones. Redshift Serverless replaces clusters with workgroups (compute) and namespaces (databases and their data).
- Each cluster comprises a leader node, which coordinates analytical queries, and compute nodes, which execute the queries. A high-speed internal network connects all the cluster nodes together to ensure high-speed communication.
- Each node is divided into slices, and each slice gets a portion of the node’s memory and disk space and processes a portion of the workload. Within each cluster are one or more databases. Redshift is based on PostgreSQL, but its implementation is different from a regular PostgreSQL implementation.
Client Applications
Redshift integrates with a large number of applications, including BI and analytics tools, which enable analysts to work with the data in Redshift. Redshift also works with Extract, Transform, and Load (ETL) tools that help load data into Redshift, prepare it, and transform it into the desired state.
Because Redshift is based on PostgreSQL, most SQL applications can work with Redshift. However, there are important differences between the regular PostgreSQL version and the version used within Redshift.
Connection Methods
Client applications can communicate with Redshift using the Amazon Redshift-specific JDBC, ODBC and Python drivers. AWS previously recommended the open-source PostgreSQL JDBC and ODBC drivers, but now recommends moving to the Redshift drivers.
Amazon first released custom ODBC and JDBC drivers optimized for Redshift in 2015, citing a performance gain of up to 35% compared to the open-source drivers at the time.
Clusters, Leader and Compute Nodes
When a user sets up an Amazon Redshift data warehouse, their core unit of operations is a cluster. A Redshift cluster is composed of one or more Compute Nodes. If a cluster has two or more Compute Nodes, Amazon automatically adds a Leader Node which is not billed to the user; you only pay for compute nodes. In a single-node cluster, one node shares the leader and compute roles, which AWS does not recommend for production. Client applications communicate only with the Leader Node. The Compute Nodes under the Leader Node are transparent to the user.
The Redshift Leader Node and Compute Nodes work as follows:
- The Leader Node receives queries and commands from client programs.
- When clients perform a query, the Leader Node is responsible for parsing the query and building an optimal execution plan for it to run on the Compute Nodes, based on the portion of data stored on each node.
- Based on the execution plan, the Leader Node creates compiled code and distributes it to the Compute Nodes for processing. Finally, the Leader Node receives and aggregates the results, and returns the results to the client application.
A few additional details about Leader and Compute nodes:
- The Leader Node only distributes SQL queries to the compute nodes if the query references user-created tables or system tables. In Redshift, these are tables with an STL or STV prefix, or system views with an SVL or SVV prefix.
- Each Compute Node has its own dedicated CPU and memory, determined by the node type. AWS now recommends two node families: RG, the Graviton-based nodes generally available since May 2026, and RA3. The older dense storage (DS2) and dense compute (DC2) node types are no longer available. Node sizes range from 2 vCPUs and 16 GiB of memory to 48 vCPUs and 384 GiB, and in a multi-node cluster each node can address 8 TB to 128 TB of Redshift Managed Storage.
- As workload grows, you can increase computing capacity and storage capacity by adding nodes to the cluster, or upgrading the node type.
- Amazon Redshift uses high-bandwidth network connections, close physical proximity, and custom communication protocols to provide private, high-speed network communication between the nodes of the cluster.
- The compute nodes run on a separate, isolated network that client applications never access directly, which also has security benefits.
For more details, see our page about Redshift cluster architecture in this guide.
Redshift Managed Storage and Redshift Serverless
RG and RA3 store warehouse data in Redshift Managed Storage (RMS), which scales to petabytes on Amazon S3, with local SSDs as a tier-1 cache. Compute and storage scale and bill independently; paused clusters bill only for backup storage.
RG is the first Graviton-based provisioned node type. AWS claims warehouse workloads run up to 2.2x as fast as RA3 at a 30% lower price per vCPU. Its integrated data lake query engine uses the cluster’s own compute; RA3 uses Redshift Spectrum.
Serverless removes node selection. Redshift Processing Units (RPUs) each provide 16 GB of memory; base capacity starts at 4 RPUs. Since April 2026, new workgroups default to AI-driven scaling and optimization with the Balanced price-performance setting. Compute bills only while in use.
Node Slices
In Redshift, each Compute Node is partitioned into slices, and each slice receives part of the memory and disk space. The Leader Node distributes data to the slices, and allocates parts of a user query or other database operation to the slices. Slices work in parallel to perform the operations.
The number of slices per node depends on the node size of the cluster, from 2 slices on the large, xlarge and xlplus sizes to 16 on rg.12xlarge and ra3.16xlarge. See the number of slices for different node types.
Within the node, Redshift can decide automatically how to distribute data between the slices (the AUTO distribution style), or you can choose EVEN or ALL distribution, or KEY distribution with one column specified as the distribution key. When you execute a query, the query optimizer on the Leader Node redistributes the data on the Compute Nodes as needed, in order to perform any joins and aggregations.
The goal of defining a table distribution key is to minimize the impact of the redistribution step, by locating the data where it needs to be before the query is executed.
When you don’t use automatic table optimization, Amazon suggests three best practices for choosing a distribution key, to help Redshift execute queries more efficiently.
- Distribute fact table and one dimension table on common columns: Your fact table can have only one distribution key. Choose one dimension to collocate based on how frequently it is joined and the size of the joining rows.
- Choose a column with high cardinality in the filtered result set: For example, if you distribute a sales table on a date column, the result is an even data distribution (unless sales are seasonal). However, if queries are typically filtered for a narrow date period, the required rows are located on only a small set of slices, and queries run slower.
- Change some dimension tables to use ALL distribution: If a dimension table cannot be collocated with the fact table or other joining tables, you can improve query performance by distributing the entire table to all of the nodes. However, there is a major drawback: using ALL distribution multiplies storage space requirements and increases load times and maintenance operations.
Automatic table optimization chooses distribution styles and sort keys, so these practices apply mainly to manually tuned tables.
Databases
User data is stored on the Compute Nodes, in one or more databases. Client applications do not access the databases directly, because the SQL clients communicate only with the Leader Node, which coordinates query execution with the Compute Nodes.
Amazon Redshift is essentially an RDBMS system, and supports online transaction processing (OLTP) functions such as inserting and deleting data. However, unlike regular RDBMS databases, Redshift is optimized for high-performance analysis and reporting of very large datasets.
Redshift is based on PostgreSQL (early documentation cited PostgreSQL 8.0.2), but it leaves out many PostgreSQL features, such as secondary indexes. Amazon Redshift and PostgreSQL have some important differences that should be taken into account.
Redshift Cost and Performance
The cost of storage and processing, and the speed at which you can execute large queries, are probably the most important criteria for selecting a data warehouse. For a side-by-side look at how Redshift compares with Google’s warehouse, see our Redshift vs. BigQuery comparison.
Cost
Redshift’s pricing model for provisioned clusters is based on node-hours plus managed storage. You choose between RG and RA3 nodes, four sizes in each family, ranging from 2 to 48 virtual CPUs and 16 to 384 GiB of RAM.
Prices vary based on the AWS Region. In US East (N. Virginia), on-demand rates range from approx. $0.38 per hour for an rg.large node to approx. $13.04 per hour for an ra3.16xlarge node (see Amazon’s pricing page for the latest pricing). If you buy reserved nodes, discounts range from about 20% with No Upfront payment to as much as 76% with All Upfront payment on a three-year term, compared to the per-hour pricing.
Storage alone at $0.024 per GB-month costs about $288 per TB per year, excluding compute. Budget separately for node-hours or RPU-hours using the warehouse pricing playbook.
| Pricing component | How it is billed | US East (N. Virginia) list price |
|---|---|---|
| RG nodes (provisioned) | Per node-hour, on demand or reserved | $0.3801 (rg.large) to $9.128 (rg.12xlarge) |
| RA3 nodes (provisioned) | Per node-hour, on demand or reserved | $0.543 (ra3.large) to $13.04 (ra3.16xlarge) |
| Redshift Managed Storage | Per GB-month, separate from compute | $0.024 per GB-month |
| Redshift Serverless | Per RPU-hour, billed per second, 60-second minimum | $0.375 per RPU-hour, from $1.50 per hour at 4 RPUs |
| Serverless Reservations | Commitment discount on RPU-hours | Up to 24% (1 year) or 45% (3 years) off |
| Concurrency scaling | Extra clusters for bursts, per second | 1 free hour of credits per day per cluster (up to 30 hours banked), then on-demand rates |
| Redshift Spectrum (RA3) | Per TB scanned in Amazon S3, 10 MB minimum per query | $5 per TB |
| Free trial | Serverless credit for new users | $300 credit, expires after 90 days |
- Prices are list prices for US East (N. Virginia), based on the Amazon Redshift Pricing Page and the AWS price list as of November 2026.
Performance
MPP, columnar storage and compression support query speed alongside these automated features:
- Result caching: Enabled by default in leader-node memory, it avoids rerunning eligible repeated queries, excluding Spectrum external tables and functions such as GETDATE.
- Automatic workload management: Redshift allocates concurrency and memory across up to eight queues with query priorities; AWS recommends automatic WLM in most cases.
- Concurrency scaling: Extra clusters handle read bursts and, on RG and RA3, writes such as COPY, INSERT, UPDATE and DELETE.
- Materialized views: Refreshes are incremental where possible, and AUTO REFRESH can run every 60 seconds, with a default interval of 300 seconds.
AWS’s RG speed figures are vendor benchmarks rather than guarantees for your workload, so test your own queries before changing node type or size.
Redshift Features and Capabilities
Below we briefly describe the following key Redshift features:
- Columnar Storage and MPP
- Compression
- Semi-Structured Data, Data Lakes and Streaming
- Management and Security
- Data Types
- Updates and Upserts
Columnar Storage and MPP Processing
Columnar Storage and MPP Processing are the basic Redshift features that enable high performance analytical query processing.
Analytical queries are typically run on multiple rows of data within the same column, as opposed to OLTP queries, which tend to process data row-by-row. In a traditional database, to sum up invoice amounts across a billion database rows, you need to scan the entire data set. Because Redshift uses a columnar structure, it can directly read the column representing the invoice amounts, and sum them up very quickly. Columnar storage not only improves query speed, but save on I/O operations, and can reduce storage size required for the same data sets.
As described in the architecture section above, Redshift employs a Massively Parallel Processing (MPP) architecture that distributes SQL operations across data slices within multiple cluster nodes, resulting in very high query performance. Redshift is also able to reorganize the data on the nodes before running a query, which dramatically boosts performance.
For more details, see our page on Redshift Columnar Storage in this guide.
Compression
Redshift automatically compresses all data you load into it, and decompresses it during query execution. Compression conserves storage space and reduces the size of data that is read from storage, which reduces the amount of disk I/O, and therefore improves query performance.
In Redshift, Compression is a column-level operation. There are several options for compressing data based on the columnar structure of the data. New tables default to ENCODE AUTO, which lets Redshift choose and adjust each column’s encoding. The options include AZ64, an Amazon-proprietary encoding for numeric, date and time data, and ZSTD.
Semi-Structured Data, Data Lakes and Streaming
Redshift also queries nested data and ingests directly from supported sources.
- SUPER and PartiQL: Store JSON, arrays and nested objects in SUPER columns, then query with PartiQL without imposing a schema first.
- Data lake queries: RA3 queries Amazon S3 through Spectrum, billed per TB scanned; RG and Serverless use their own compute. Redshift reads and writes Apache Iceberg data lake tables, with row-level UPDATE, DELETE and MERGE added in April 2026.
- Streaming ingestion: Amazon Kinesis Data Streams or Amazon Managed Streaming for Apache Kafka loads directly into materialized views at hundreds of megabytes per second.
- Zero-ETL integrations: Replicate from Aurora MySQL and PostgreSQL, DynamoDB, RDS for MySQL, PostgreSQL and Oracle, plus Salesforce, SAP, ServiceNow and Zendesk, without building an ETL pipeline.
- Data sharing and Redshift ML: Share live data across warehouses, with multi-warehouse writes generally available since November 2024. CREATE MODEL trains through Amazon SageMaker AI without additional Redshift charges, though training is billed separately; SQL can also call Amazon Bedrock foundation models.
Management and Security
Redshift is a managed service from Amazon, meaning that most of the ongoing tasks and concerns in a traditional data warehouse are taken care of:
- Managed infrastructure: Amazon provides the physical hardware, configuration, networking, and ongoing maintenance to ensure the data warehouse runs and performs optimally. Redshift also runs VACUUM DELETE and table sorting automatically in the background, during periods of low load. VACUUM is a command that removes rows that are no longer needed in the database, and re-sorts the data; you can still run it manually after large loads. Amazon also doesn’t take responsibility for optimizing performance on the nodes for users’ specific queries or workloads.
- Backup and failover: Data stored in Redshift is automatically backed up. Incremental snapshots are maintained in S3, taken about every eight hours or after every 5 GB per node of data changes, kept for 1 to 35 days on RG and RA3 clusters, and can be restored. Amazon monitors the health of the Redshift cluster, re-replicates data from failed drives and replaces nodes as necessary. For additional resilience, provisioned RG and RA3 clusters can run as a Multi-AZ deployment, with compute in two Availability Zones behind one endpoint, at the same hourly rates.
- Encryption: New Redshift clusters and Serverless workgroups are encrypted at rest by default, with an AWS-owned key unless you choose your own AWS KMS key. Since January 2025, new warehouses also default to public access turned off.
- SSL: Connections between clients and Redshift can be encrypted, and new warehouses require SSL by default. Redshift uses hardware-accelerated SSL while loading data from Amazon S3 or DynamoDB, during import, export, and backup.
- Virtual Private Cloud (VPC): Redshift leverages Amazon’s VPC infrastructure, and RG and RA3 clusters launch in a VPC, enabling you to protect access to your cluster by using a private network environment within the Amazon data center.
- Access control: Beyond network controls, Redshift supports row-level security policies and column-level grants.
See Redshift’s security overview for more details and options.
Data Types
Redshift supports a wide range of classic data types, plus newer types for time, semi-structured, binary and spatial data, listed below:
| Data Type | Description |
|---|---|
| SMALLINT | Signed two-byte integer |
| INTEGER | Signed four-byte integer |
| BIGINT | Signed eight-byte integer |
| DECIMAL | Exact numeric of selectable precision |
| REAL | Single precision floating-point number |
| DOUBLE PRECISION | Double precision floating-point number |
| BOOLEAN | Logical Boolean (true/false) |
| CHAR | Fixed-length character string |
| VARCHAR | Variable-length character string with a user-defined limit |
| DATE | Calendar date (year, month, day) |
| TIMESTAMP | Date and time (without time zone) |
| TIMESTAMPTZ | Date and time (with time zone) |
| TIME | Time of day (without time zone) |
| TIMETZ | Time of day (with time zone) |
| INTERVAL YEAR TO MONTH, INTERVAL DAY TO SECOND | Duration in years and months, or in days to seconds |
| SUPER | Semi-structured data, including arrays and nested objects |
| VARBYTE | Variable-length binary value, up to 16 MiB |
| GEOMETRY, GEOGRAPHY | Spatial data |
| HLLSKETCH | HyperLogLog sketch for approximate distinct counts |
The DECIMAL (also called NUMERIC) data type stores values with user-defined precision. Precision is important for exact numeric operations, such as in financial operations.
For more details see our extensive blog post on challenges and best practices of Redshift data types.
Updates and Upserts
Amazon does advertise Redshift as a fully-featured RDBMS, but because it is highly optimized for analytical queries, updates and upserts are not trivial operations.
Redshift supports UPDATE and DELETE SQL commands, and since April 2023 it also provides a MERGE command that updates, deletes or inserts rows in a target table from a single source table or query. You can still perform a merge operation by loading the updated data to a staging table, and then update the target table from the staging table. For more details, see the Redshift documentation page on updating and inserting.
Performing a large number of updates and deletes leaves behind deleted rows and unsorted data, which slows queries over time. Redshift reclaims that space with automatic VACUUM DELETE in the background, and a manual VACUUM operation reclaims space and re-sorts rows in either a specified table or all tables in the current database. Running a VACUUM command without the necessary table permissions completes but has no effect.
Redshift Challenges
Amazon Redshift is a powerful service, and AWS has automated many of the tasks that used to need hands-on care. However, users still experience complexity when setting up and running Redshift:
- Loading data to Redshift is non-trivial for sources outside AWS’s zero-ETL integrations and streaming ingestion. For large-scale data pipelines, loading data to Redshift requires setting up, testing and maintaining an ETL or ELT process.
- Updates, upserts and deletions can be tricky in Redshift and must be done carefully to prevent degradation in query performance.
- Semi-structured data no longer has to be normalized before loading, thanks to SUPER and PartiQL, but JSON that is queried often still benefits from being shredded into typed columns or materialized views.
- Sizing and cost control: There are many options for setting up Redshift, from node family and size to Serverless base capacity and price-performance settings. Different workloads, data sets, or even different types of queries might require a different setup. To stay optimal, you need to revisit your configuration and track usage as workloads change.
- Query optimization: User queries may not follow best practices, and consequently take much longer to run. You may find yourself working with users or automated client applications to optimize queries, so that Redshift can perform as expected.
- Backup and recovery: While Amazon automates snapshots, choices such as retention periods, cross-Region snapshot copies and Multi-AZ still need planning, monitoring and close attention.
- Python UDFs: Redshift ended support for Python user-defined functions after June 30, 2026. Move existing logic to Lambda UDFs or SQL.
Many teams handle loading with a managed ELT service such as Fivetran or Airbyte, or with AWS Glue, and transform data inside the warehouse with dbt. The ETL tools chapter compares the options. If Redshift’s tuning work outweighs its AWS integration, Snowflake, BigQuery and Databricks are the usual alternatives to compare in the directory.
Common questions
What are the main components of Redshift architecture?
Redshift architecture connects client applications to a leader node, which plans queries for compute nodes split into slices. An internal network connects the nodes, while databases organize the data. On RG and RA3, Redshift Managed Storage on Amazon S3 holds warehouse data separately from compute, with local SSD caching.
How much does Amazon Redshift cost?
In US East (N. Virginia), provisioned nodes cost about $0.38 to $13.04 per node-hour, plus $0.024 per GB-month of storage. Serverless compute costs $0.375 per RPU-hour, starting at $1.50 per hour. Reserved nodes offer up to 76% off; new Serverless users can receive a $300 trial credit expiring after 90 days.
Should I use Redshift Serverless or a provisioned cluster?
Serverless suits spiky or unpredictable workloads and teams that do not want to size nodes, with compute billed per second only while in use. Provisioned RG or RA3 clusters suit steady, predictable workloads where reserved nodes cut the hourly rate.
Does Redshift support MERGE and upserts?
Yes. Redshift has supported MERGE since April 2023 for updates, deletes and inserts from a source table or query. Staging-table methods still work. Automatic VACUUM DELETE reclaims deleted-row space; manual VACUUM remains available.
Where to next
Read Redshift Columnar Storage 101 for storage mechanics and Redshift Cluster 101 for cluster design. Compare data warehouse architecture with BigQuery architecture, then use Data Mart vs. Data Warehouse to decide how much data belongs in your warehouse.
Snowflake, BigQuery, Redshift, Databricks, Fivetran, Airbyte and the rest, with pricing and what each one replaces.
Browse the tools