Quick answer:
ETL extracts source data, transforms it through validation and cleansing, then loads a target such as a data warehouse. This ETL tutorial covers the six-step process, five reusable recipes and a working Python and SQL pipeline with a Type 4 history table.
Most new cloud stacks load first and transform in the warehouse (ELT). ETL still fits when masking must happen before data lands.
The Extract Transform Load (ETL) process has a central role in data management at large enterprises. Whenever data makes the transition from production OLTP applications to OLAP and analytics applications, it needs to be extracted from the source system, transformed into a shape, form and structure suitable for the target system, and loaded into the target system.
It’s difficult to provide a comprehensive ETL tutorial, because ETL is different in every organization. There is also a wide variety of tools that help organizations manage and automate ETL. In this guide, we’ll provide an overview of what ETL is, and a few generic examples of key ETL tasks, such as data extraction, header and trailer processing and data masking, which you can apply to your specific environment.
After the recipes, a Python and SQL walkthrough builds the first one end to end, followed by the most common ETL mistakes and a look at ELT.
What is ETL?
Extract Transform Load (ETL) is a process which prepares raw data for consumption by enterprise systems, typically for reporting and analytics purposes. A common use case for ETL is in the data warehouse. ETL processes prepare OLTP data, for example day-to-day transaction data from finance, ERP or CRM, to be loaded into a data warehouse for reporting and exploration by BI tools.
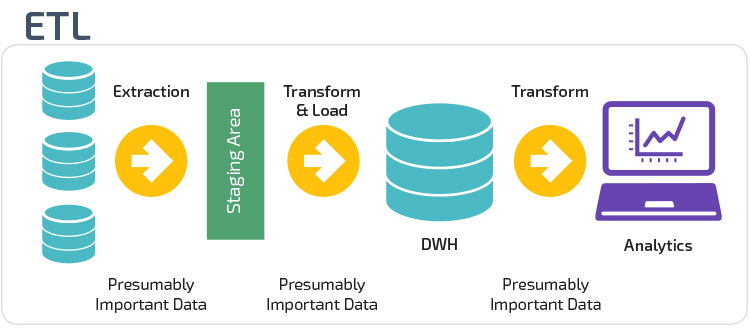
ETL tools have been around for more than two decades, and are extremely helpful in defining and automating complex ETL processes. Incumbent ETL tools include Informatica, now owned by Salesforce, and IBM DataStage. Stitch, one of the early cloud tools that set up pipelines in a few clicks, is now part of Qlik through its Talend acquisition, alongside Talend itself. Most teams starting today pair a managed or open-source loader such as Fivetran or Airbyte with dbt for transformations.
The ETL Process
The traditional ETL process is based on batch processing. ETL jobs run daily, weekly or monthly, and process large volumes of data from source systems. Many pipelines now also run in micro-batches every few minutes, or stream row-level changes with change data capture (CDC) tools such as Debezium, which read the source database’s transaction log.
The steps stay the same either way. Here are the basics of the ETL process:
- Reference data: Create a set of reference data that defines permissible values your data may contain
- Data extraction: Extract data from sources, converting it from multiple formats like RDBMS, XML, JSON, CSV, etc. to a single standardized format
- Data validation: Validate data to ensure it contains the expected information in the correct format, otherwise subsequent ETL steps will not work
- Data transformation: Transform data by cleaning it, verifying its integrity, and aggregating or restructuring it to facilitate easy analysis
- Staging: Load data to a staging environment, to make it easier to roll back if something goes wrong
- Load to data warehouse: If everything looks good, push the data to your production data warehouse, either overwriting older data, or retaining it and managing historical versions with timestamps
ETL Examples: Common ETL Tasks
Following are a few generic examples of key ETL tasks. You can treat these examples as recipes, and implement them using your specific ETL tool or environment.
Data Extraction
Data extraction is the first step in the ETL process. Data extraction can take many different forms: data can be copied directly from storage devices, loaded via APIs, streamed via tools like Kafka, etc. Consider a simple example of data files uploaded to an FTP server, which need to be loaded to a target table in a data warehouse.
The recipe below uses a Type 4 Slowly Changing Dimension: data that is modified is stored in a separate history table with a timestamp for each historic version.
To extract source data transferred via FTP, while managing previous versions of the data:
- Maintain two tables: the target data table, and a history table, with previous, timestamped versions of each data field.
- Create an automatic trigger that detects a new file in a designated folder on the FTP server and pulls it to the ETL machine.
- Load data from the source file to a temporary table.
- Load the existing target table to a temporary lookup file.
- For each record in the source file, do the following:
- Validate the source data record and if it doesn’t pass validation, save it to a reject table (see the data quality recipe below).
- Check the record against the lookup table. If it does not exist, load to target table as a new record.
- If the record does exist in the lookup table, and the value has changed, save the previous value to the history table with a timestamp, and then load the new value to the target table, overwriting the previous value. If value has not changed, do nothing.
The walkthrough below builds this recipe in Python and SQL, with the history insert and the merge in one transaction.
Surrogate Key Generation
A surrogate key is a data field added by ETL engineers to manage data coming in from multiple sources. The surrogate key is a unique, numeric record identifier, which is mapped to original “natural keys” in the source data, such as customer IDs or transaction IDs.
To load data while generating a surrogate key, overwriting existing data:
- Select natural keys in the source data.
- Create a mapping table that maps all values of the natural keys to the new, numeric surrogate key. The table should include a value that denotes the maximum key number of the last data field loaded.
- Execute a loading process for each of the source files:
- Validate that the mapping table correctly maps all values of the source data.
- For each data record, check if the surrogate key already exists in the target table. If so, overwrite the same record.
- If surrogate key does not exist, add a new entry to the mapping table, add a new record to the target table, and increment the maximum key by 1.
A similar, slightly more complex process can be designed to load data while keeping a historical version of the data.
Header and Trailer Processing
Many data sources, including legacy sources and network traffic data, have records arranged in blocks with a header containing standard descriptive data, and a trailer at the end of each block.
To process header and payload:
- This type of processing is most easily performed using an ETL processing tool. Using a tool of your choice, extract the data, adding a separator within the file indicating header, body and trailer parts of the data.
- Using the separators, break the data into three tables: headers, body, and trailers.
- Refer to documentation of header and trailer format and convert into a usable form in the header and trailer tables.
- Make sure you retain a record ID that maps body data to headers and trailers.
Data Masking
It is a common requirement in data projects to mask, scramble or anonymize data. This might be necessary:
- When testing or staging data (to prevent sensitive customer data from being stored on non-production servers).
- When moving OLTP data to a data warehouse, the data might have to be anonymized to reduce privacy and security concerns, while still retaining the business-relevant information in each data record.
Strategies for masking or anonymizing data:
- Substitution: replacing each value in a sensitive data field with fake data from a dictionary table.
- Masking: adding characters like * to replace sensitive data. For example, representing a 16-digit credit card number with 12 asterisks, retaining only the last 4 digits.
- Hashing: using a one-way function such as SHA-256 to turn the sensitive data value into a completely different, fixed-length value. The same input always gives the same hash, so joins still work, but the output does not keep the original size or format, and short or predictable values such as phone numbers can be guessed by brute force.
- Format-preserving encryption or tokenization: replacing the value with one in the same format, so a 16-digit card number stays 16 digits and downstream schemas and validation rules keep working. Format-preserving encryption (the FF1 method in NIST SP 800-38G) is reversible with a key; tokenization swaps the value for a token, with the mapping held in a secure vault or derived from a key.
- Shuffling: switching data randomly between data records.
- Randomization: randomly generating data to replace the original sensitive data.
Data Quality and Data Cleansing
Any ETL process is required to validate consistency and integrity of the data, and clean erroneous or non-standard data records. This is a crucial step which can undermine all subsequent processing steps, if not done correctly.
Consider a simple data quality process including two tests:
- Syntax test: identifying records that have an incorrect data pattern, invalid characters, incorrect data types, etc.
- Reference test: identifying records that have a correct data pattern but do not match up with known reference data, for example, an order including a product which does not exist in the products table.
To create an automated data cleansing process:
- For dates, check if date is in the correct format and satisfies business rules (for example, orders should be from the past week).
- For IDs, check if they contain correct characters and are in the acceptable range of numbers or characters.
- For addresses, check syntax and also check components of the address against a dictionary table of country, city and street names.
- For phone numbers, check format, allowing for international number formats, and check country codes against a dictionary table of acceptable countries.
- Similar checks for any other data field.
- Save all data fields with errors to a rejects file, to enable troubleshooting and manual data correction.
- For any data issue found, report a warning if the issue is not critical, and save the data to target table. Report an error if the issue is critical, and do not save the data to the target table.
Build a Simple ETL Pipeline: Python and SQL Walkthrough
Build the Data Extraction recipe with Python and SQL on PostgreSQL 15 or later. Assume customers.csv has landed on the FTP server, with columns customer_id, email, tier and updated_at.
Step 1: Create the Tables
Create current and history tables, plus a typed staging table without key or not-null constraints.
CREATE TABLE customer (
    customer_id integer PRIMARY KEY,
    email       text NOT NULL,
    tier        text NOT NULL,
    updated_at  timestamptz NOT NULL
);

CREATE TABLE customer_history (
    customer_id integer NOT NULL,
    email       text NOT NULL,
    tier        text NOT NULL,
    valid_from  timestamptz NOT NULL,
    valid_until timestamptz NOT NULL
);

CREATE TABLE stg_customer (
    customer_id integer,
    email       text,
    tier        text,
    updated_at  timestamptz
);
Step 2: Extract and Stage the File with Python
Use psycopg 3 and Python’s standard csv module.
import csv
import os
from datetime import datetime

import psycopg  # psycopg 3: pip install "psycopg[binary]"

rows, rejects = [], []
with open("customers.csv", newline="", encoding="utf-8") as f:
    for r in csv.DictReader(f):
        email = r["email"].strip().lower()
        if not r["customer_id"].isdigit() or "@" not in email:
            rejects.append(r)
            continue
        rows.append((int(r["customer_id"]), email, r["tier"].strip(),
                     datetime.fromisoformat(r["updated_at"])))

with psycopg.connect(os.environ["WAREHOUSE_DSN"]) as conn, conn.cursor() as cur:
    cur.execute("TRUNCATE stg_customer")
    cur.executemany(
        "INSERT INTO stg_customer (customer_id, email, tier, updated_at) "
        "VALUES (%s, %s, %s, %s)",
        rows,
    )

print(f"staged {len(rows)} rows, rejected {len(rejects)}")- Bind values safely:
%sparameters prevent file contents from becoming executable SQL. - Keep credentials outside code: set
WAREHOUSE_DSNto your PostgreSQL connection string. - Persist rejects: failed ID/email checks collect rows in
rejects; write them to durable storage in production. TRUNCATE and INSERT commit together when the connection block exits, so failure leaves staging unchanged.
Use timezone-bearing ISO timestamps, such as 2026-11-01T12:00:00+00:00. Invalid timestamps abort this script; catch them explicitly in production validation.
Step 3: Write History and Merge in One Transaction
Initialize etl_watermark using the setup statements under Incremental Loads and Idempotency, then execute:
BEGIN;

CREATE TEMP TABLE stg_latest ON COMMIT DROP AS
SELECT customer_id, email, tier, updated_at
FROM (
    SELECT s.*,
           ROW_NUMBER() OVER (PARTITION BY customer_id ORDER BY updated_at DESC) AS rn
    FROM stg_customer AS s
) AS ranked
WHERE rn = 1;

INSERT INTO customer_history (customer_id, email, tier, valid_from, valid_until)
SELECT c.customer_id, c.email, c.tier, c.updated_at, s.updated_at
FROM customer AS c
JOIN stg_latest AS s ON s.customer_id = c.customer_id
WHERE s.updated_at > c.updated_at
  AND (c.email IS DISTINCT FROM s.email OR c.tier IS DISTINCT FROM s.tier);

MERGE INTO customer AS c
USING stg_latest AS s
ON c.customer_id = s.customer_id
WHEN MATCHED AND s.updated_at > c.updated_at
             AND (c.email IS DISTINCT FROM s.email OR c.tier IS DISTINCT FROM s.tier) THEN
    UPDATE SET email = s.email, tier = s.tier, updated_at = s.updated_at
WHEN NOT MATCHED THEN
    INSERT (customer_id, email, tier, updated_at)
    VALUES (s.customer_id, s.email, s.tier, s.updated_at);

UPDATE etl_watermark
SET last_loaded_at = COALESCE((SELECT max(updated_at) FROM stg_latest), last_loaded_at)
WHERE job_name = 'customers';

COMMIT;- Deduplicate first:
stg_latestkeeps the latest row per customer. Multiple matches can make MERGE fail; resolve timestamp ties deterministically. - Archive before updating: the history INSERT captures previous values until the incoming timestamp. MERGE targets one table; both statements share a transaction.
- Skip repeated changes: timestamp and null-safe value comparisons prevent duplicate history on replay. Run one job at a time against these shared tables.
This snapshot recipe discards intermediate changes within each batch. It also assumes files arrive in timestamp order. A row whose values haven’t changed doesn’t advance customer.updated_at, so an older file loaded late could still slip past the timestamp check.
This separate-history pattern is commonly called SCD Type 4. Kimball’s Type 4 means a mini-dimension; Type 2 stores history within the dimension table.
Running It on Snowflake or BigQuery
- PostgreSQL 15 and 16: MERGE lacks RETURNING and WHEN NOT MATCHED BY SOURCE; both arrived in 17. Handle deletes separately. Use
SET email = s.email, notSET c.email = .... - Snowflake: use
BEGIN TRANSACTION ... COMMITandTIMESTAMP_TZ. Buildstg_latestbefore BEGIN: DDL commits open transactions.ERROR_ON_NONDETERMINISTIC_MERGEdefaults to true. - BigQuery: use
BEGIN TRANSACTION; ... COMMIT TRANSACTION;,TIMESTAMPand dataset-qualified names. Transactions can mutate up to 100 tables. Buildstg_latestbeforehand. - Databricks: MERGE INTO requires Delta tables.
Incremental Loads and Idempotency
For database sources, extract changes since a saved watermark. Run CREATE and INSERT once before Step 3; run SELECT against the source, binding %(since)s through psycopg.
CREATE TABLE etl_watermark (
    job_name       text PRIMARY KEY,
    last_loaded_at timestamptz NOT NULL
);
INSERT INTO etl_watermark VALUES ('customers', '1970-01-01T00:00:00Z');

SELECT customer_id, email, tier, updated_at
FROM app.customers
WHERE updated_at >= %(since)s
ORDER BY updated_at;
Step 3 updates the watermark within the load transaction, so failure leaves it unchanged. Use >= to reread boundary rows; replaying the same input leaves current and history rows unchanged. That is idempotency: the same input produces the same result.
Run twice and compare staging, current and history counts. Index source updated_at. Watermarks miss hard deletes and can miss clock-skewed updates; Debezium instead reads PostgreSQL’s write-ahead log through logical decoding and resumes from its recorded position.
Common ETL Mistakes to Avoid
Duplicate rows often appear on the second run, after the first load succeeded.
- Non-idempotent loads: blind INSERTs duplicate rows on reruns. Merge on a stable business key and run the same input twice, as in the walkthrough.
- Skipping deduplication in staging: duplicate keys inflate metrics or make MERGE fail. Keep one row per key and resolve timestamp ties deterministically.
- Trusting source schemas: schema drift can silently lose data. Check column names and types before loading, starting with the syntax test recipe.
- Reading only the first page of a paginated API: the job succeeds with partial data. Follow next-page tokens until the API indicates completion.
- Running heavy extracts on the production primary: large scans compete with application queries. Use a replica or log-based CDC and monitor source impact.
- Credentials in code: passwords survive in repository history. Use environment variables or a secrets manager; rotate leaked credentials.
- NOW() inside load logic: results change with execution time, making backfills unreliable. Pass the intended run date or watermark as a parameter.
- Copying dirty data unchanged: source errors become dashboard errors. Apply the data quality recipe, preserve rejects and alert operators to failures.
Going Beyond ETL with ELT and Automated Data Management
Traditional ETL processes are the standard in many large organizations. But they are complex to build and test, and cumbersome to maintain. Many organizations are moving to new data warehouse infrastructure that supports Extract Load Transform (ELT).
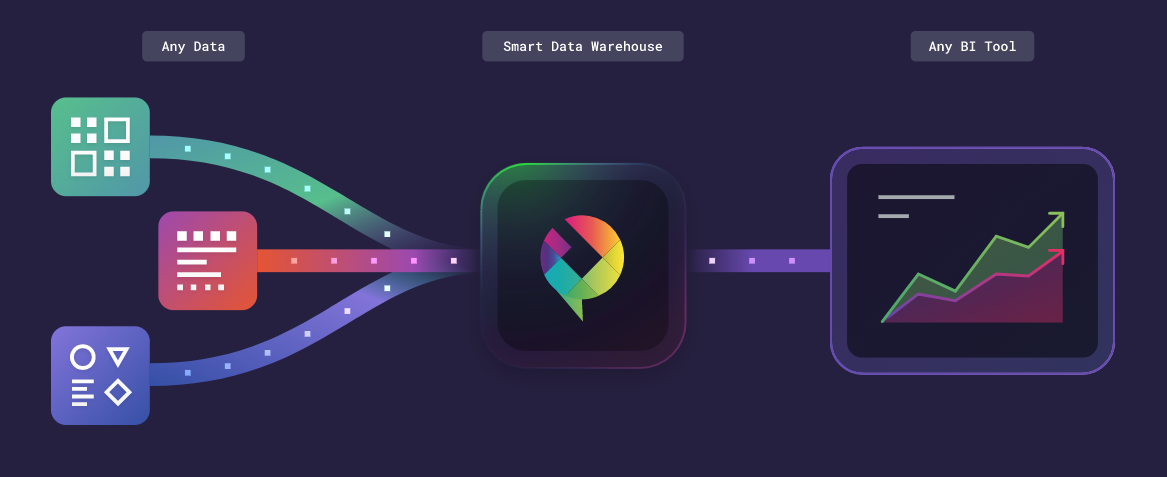
In ELT, you simply load all data directly to the data warehouse, and then transform it later on-the-fly according to user requirements. This requires the ability to store large volumes of data and perform complex processing quickly, even when data is not pre-organized according to known queries. New data warehouse technology provides these capabilities.
ETL vs ELT in Practice
In ELT, Fivetran or Airbyte loads raw tables; SQL models, often managed with dbt, transform them inside the warehouse. Fivetran and dbt Labs completed their merger on 1 June 2026. The walkthrough is already ELT-shaped: Python validates rows, then SQL handles history and merging inside the database.
ETL before the load still wins when:
- PII must never land raw: Snowflake masking policies (Enterprise Edition or higher) and BigQuery data policies mask values at query time, but the real values are still stored in the warehouse. If that isn’t allowed, apply the Data Masking recipe before loading.
- Compliance requires curated tables only: governance rules may prohibit raw copies of regulated data in analytics systems, even with restricted access.
- The transform is not SQL: binary header/trailer parsing or per-record API calls may need Python outside the warehouse.
- Raw volume is expensive to keep: filtering before loading reduces storage and downstream processing.
A hybrid validates and masks in flight, then leaves SQL-friendly transformations to the warehouse.
Compare loaders and transformation tools in the ETL Tools chapter, or browse the directory below for pricing. Consult the ETL and ELT glossary entries for definitions. Continue to ETL testing to check correctness, not just successful execution.
FAQ
What is the difference between ETL and ELT?
ETL transforms data before loading it into a warehouse; ELT loads raw data first and transforms it inside the warehouse, usually with SQL and dbt. ELT is the usual starting point for new cloud stacks. Choose pre-load ETL when sensitive data must not land raw. See ETL vs ELT in Practice above.
Is ETL still relevant?
Yes, ETL remains relevant when transformation must precede loading, especially for PII masking and legacy file processing. Cloud pipelines often combine these tasks with warehouse-side SQL transformations. The recipes apply to both patterns: changing where processing happens does not remove validation or history requirements.
Do I need Python for ETL, or is SQL enough?
SQL covers most warehouse transformations and loads, including the walkthrough’s MERGE. Python helps extract files or APIs and handle logic awkward in SQL. For a few gigabytes, pandas can be practical if memory permits. For larger workloads, consider warehouse SQL or DuckDB; distributed processing may justify PySpark.
What is a Type 4 slowly changing dimension?
In common tutorial usage, a Type 4 slowly changing dimension keeps current records in one table and previous versions in a separate, timestamped history table. The Data Extraction recipe uses that meaning. Kimball’s catalog instead uses Type 4 for mini-dimensions containing fast-changing attributes; Type 2 keeps historical versions as additional rows in the dimension table itself.
Snowflake, BigQuery, Redshift, Databricks, Fivetran, Airbyte and the rest, with pricing and what each one replaces.
Browse the tools