Quick answer:
A data warehouse collects data from across the business and stores it cleaned and structured for analysis. Data mining uses techniques such as association rules, classification, clustering, anomaly detection and forecasting to search that data for patterns nobody asked about in advance.
The distinction between data warehousing and data mining is plumbing versus analysis: the warehouse prepares and stores the data, while mining searches it for useful insights. Today, much of that analysis can run inside cloud warehouses such as Snowflake, BigQuery, Amazon Redshift and Databricks through SQL functions, without exporting the data.
In physical mining of minerals from the earth, miners use heavy machinery to break up rock formations, extract materials, and separate them from their surroundings.
In data mining, the heavy machinery is a data warehouse: it helps to pull in raw data from sources and store it in a cleaned, standardized form, to facilitate analysis. To continue the analogy, like mining engineers follow precise processes to extract precious stones from the surrounding dirt, data mining is a collection of techniques for sifting through raw data and discovering precious insights that can make a difference to the business.
What is a Data Warehouse?
A data warehouse is a relational database that stores historic operational data from across an organization, for reporting, analysis and exploration. Data warehouses are built to store very large volumes of data, and are optimized to support complex, multidimensional queries by business analysts and data scientists.
Most new warehouses are cloud services such as Snowflake, Google BigQuery, Amazon Redshift and Databricks, which store data in columns and scale storage and compute separately. Data reaches them through ETL or ELT pipelines that copy it from apps and databases. The ETL tools overview covers that step. Some teams keep raw files in a data lakehouse and query them with the same engines.
What is Data Mining?
Data mining involves deriving insights from large data sets. As its name metaphorically suggests, data mining is a process of carefully reviewing and processing large quantities of data (the “dirt”) to discover important patterns, findings or correlations (the “diamonds”) which might be important for the business.
In physical mining, it’s very difficult and time consuming to manually sift through dirt to find precious stones. Automatic tools make it easier to cover much more ground and go deeper into the earth in search of jewels. In data mining too, automation is essential to speed up the process, and go deeper in the breadth of data to derive insights.
Common uses of data mining include analysis and predictive modeling for marketing campaigns, pricing, fraud detection, financial forecasting, and analyzing website traffic.
The term data mining overlaps heavily with machine learning and data science. Data mining names the goal, finding useful patterns in large data sets, while machine learning supplies many of the methods used to reach it. Statisticians, analysts and data scientists all do data mining, even when their job titles never use the phrase.
Key Differences Between Data Warehousing and Data Mining
Data warehousing and data mining depend on each other, but differ in where they sit in the processing pipeline, who performs them and their purpose.
Stages in the Data Processing Pipeline
- The data warehousing stage involves collecting data, organizing it, transforming it into a standard structure, optimizing it for analysis and processing it.
- The data mining stage involves analyzing data to discover unknown patterns, relationships and insights.
Organizational Roles
- Data warehousing is part of the “plumbing” that facilitates data mining, and is taken care of primarily by data engineers and IT.
- Data mining is performed by business analysts or data scientists who have a deep understanding of the data.
Objectives
- Data warehousing is intended to provide the organization with a reliable source of data for many types of business analysis.
- Data mining is intended to provide the organization with hidden insights that cannot otherwise be gleaned from large-scale data.
Data Warehousing vs. Data Mining at a Glance
The table connects those differences to the tools teams use and the outputs they produce.
| Data warehousing | Data mining | |
|---|---|---|
| Main question | Where is the data, and can we trust it? | What patterns does the data hide? |
| Work involved | Ingestion, cleaning, modeling, storage, access control | Selecting data, building and testing models, explaining results |
| Typical roles | Data engineers and IT | Business analysts and data scientists |
| Typical tools | Snowflake, BigQuery, Amazon Redshift, Databricks, Fivetran, Airbyte, dbt | SQL, Python, BigQuery ML, Redshift ML, Snowflake ML Functions, KNIME, Alteryx |
| Output | Clean, documented tables | Models, scores, segments and findings |
Three Data Mining Principles
1. Information discovered must be previously unknown
It should be unlikely that the information discovered in data mining could have been hypothesized in advance. The data miner looks for something that is not intuitive: the further the information is from being obvious, the more valuable it is.
2. Information must be valid
Data miners should avoid spurious results that are not statistically or empirically valid. It is sometimes difficult to prove validity in data mining, but practitioners should aim to achieve the highest possible fit between model and analyzed data.
In practice, validity checks use data the model never saw during training, through a hold-out set or cross-validation. A pattern that holds only on the training data may be noise rather than a useful finding. Teams also check for data leakage, where a column quietly contains the answer the model is meant to predict.
3. Information must be interesting or actionable
Some data mining tasks can produce thousands or millions of patterns, which are mostly redundant or irrelevant. Data miners should try to find the patterns or structures that are the most interesting for the business’s goals, based on statistical measures like frequency and subjective analysis.
Common Data Mining Analyses and Their Business Applications
Association Rules
- Definition: Objects that satisfy condition X are also likely to satisfy condition Y
- Business applications: Market basket analysis, cross selling/up selling, catalog design, store layout, financial forecasting, diagnosing likelihood of illness
Sequential Pattern
- Definition: Discovery of frequent subsequences in a collection of sequences, treating sequences with a different order separately
- Business applications: Marketing funnel analysis, natural disaster forecast, web traffic analysis, DNA analysis
Classification/Regression
- Definition: Discovery of a model or function that maps objects into classes or suitable values
- Business applications: Classification of customers for credit approval or selective marketing, performance prediction, diagnosing illness from known symptoms
Clustering
- Definition: Grouping objects so that objects in the same group are more similar to each other than to objects in other groups, without predefined labels
- Business applications: Customer segmentation, grouping products or stores by behavior, document grouping, image compression
Anomaly Detection
- Definition: Identifying records or events that differ sharply from the normal pattern in the data
- Business applications: Fraud detection, network intrusion detection, equipment failure warnings, spotting data quality errors
Time-Series Forecasting
- Definition: Predicting future values of a measure from its past values, trend and seasonality
- Business applications: Demand and inventory planning, revenue forecasting, staffing, energy load forecasting
Machine Learning and NLP Methods: The Intelligence Behind Data Mining
A key type of automation used in data mining projects is machine learning and natural language processing (NLP). These techniques make it possible to identify patterns and predict outcomes within large data sets.
Decision Trees
A series of IF/THEN rules that can be used for classification and prediction, typically in a supervised learning environment. A model is trained on a data set with known outcomes, and then attempts to apply the same decision structure to new, unknown data.
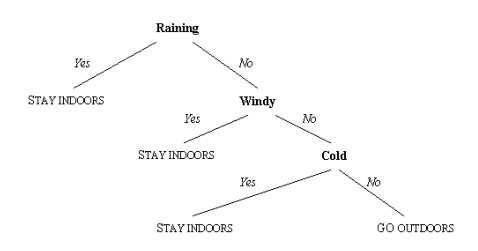
Decision tree algorithms include: CART, ID3, C4.5, C5.0, CHAID, Decision Stump, Conditional Decision Trees, M5
Supervised Machine Learning
Engines that train on a data set (input variable) with a known outcome (output variable), and iteratively make predictions until they arrive at a function that accurately maps the data set to the outcomes. The engines then apply the function to new data and can predict the outcome.
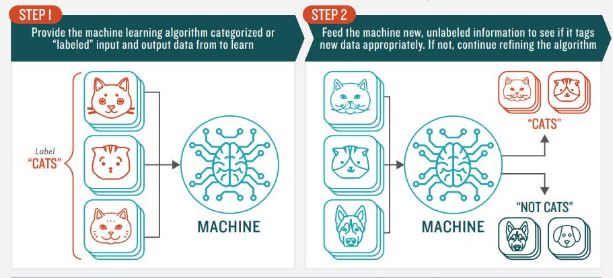
Supervised machine learning algorithms:
- Classification algorithms: Used when the output variable is a category such as “cats”, “dogs” and “mice”: Logistic Regression, Naive Bayes, k-Nearest Neighbors, Support Vector Machines, Random Forests, Gradient-Boosted Trees such as XGBoost
- Regression algorithms: Used when the output variable is a quantitative value such as “$2.4” or “45%”: Linear Regression, OLSR, Stepwise Regression, MARS, LOESS, Gradient-Boosted Regression Trees
Unsupervised Machine Learning
Engines that work on input data without a corresponding outcome (output variable), and can be used to model the underlying structure of the data set. There is no correct answer: the algorithm is tuned to derive meaningful structure from the data.
Unsupervised machine learning algorithms:
- Clustering algorithms: Used to discover inherent groupings in the data, for example grouping movie lovers by the genre of movie they prefer: K-Means, DBSCAN, Hierarchical Clustering, Gaussian Mixture Models, Self-Organizing Map
- Association algorithms: Used to discover a rule that accurately describes the data, for example products frequently purchased together: Apriori, Eclat, FP-Growth
Deep Learning / Neural Networks
Learning systems which simulate the human brain by creating large networks of digital “neurons” and using them to process pieces of a large data set. Learning systems can take in unstructured data sets, such as pixels of images, written documents or audio data, automatically recognize and extract features and classify them. Deep learning is used for a huge variety of tasks including face recognition, automatic translation and summarization, and pattern recognition.
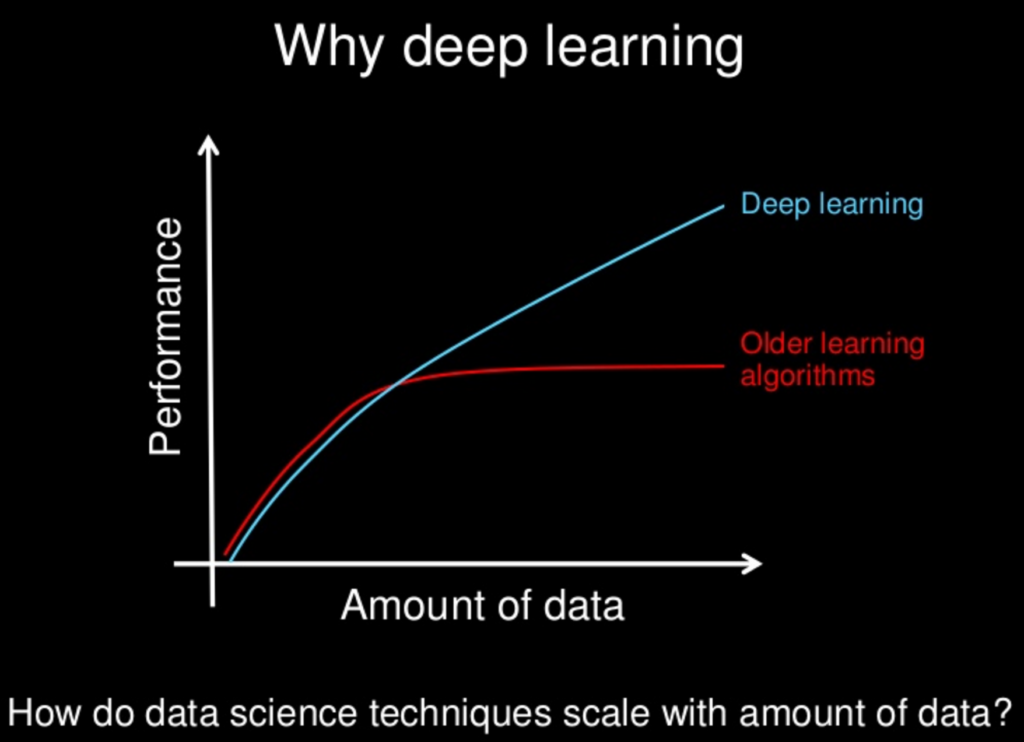
Deep learning algorithms: Multi-Layer Perceptron Networks, Convolutional Neural Networks, Long Short-Term Memory Recurrent Neural Networks, Transformers
Natural Language Processing (NLP)
NLP is a general term for the automated processing of human language. Modern NLP technology uses primarily machine learning techniques to process human language, parse it, break it down into sentences and words, and understand semantics.
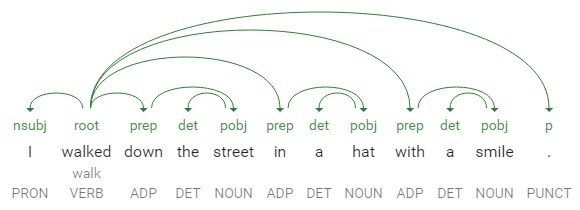
In the context of data mining, some common applications of NLP are:
- Entity extraction: Detecting names and concepts in large volumes of text
- Sentiment analysis: Understanding the emotion embedded in language, for example positive vs. negative reviews
- Relationship extraction: Understanding relations between elements in a data set
- Topic recognition / tagging: Automatically classifying material into topics or categories
- Disambiguation: Understanding what is the contextually-appropriate meaning for a word that has multiple meanings
- Summarization: Automatically generating a reliable summary of a chunk of text
Since 2018, transformer models have become central to these tasks, and large language models now handle them from written instructions rather than a separately trained model per task. Warehouses expose this through SQL on text stored in tables: Snowflake offers AI_CLASSIFY, AI_SENTIMENT, AI_EXTRACT and AI_SUMMARIZE_AGG, while Databricks offers ai_classify, ai_extract, ai_summarize and ai_analyze_sentiment. Text can also become embeddings stored in a vector database to find similar documents.
The second data mining principle still applies. Language models can produce confident but wrong answers, known as hallucination. A sample of their output needs checking against labeled examples before the results feed a report or a business decision.
Data Mining Process When Using a Data Warehouse
Data mining projects do not require a data warehouse infrastructure. But large organizations usually perform data mining on top of data stored in the data warehouse, according to the following general process:
- Data ingestion: Data engineers load relevant data into the data warehouse
- Data selection: Data engineers select relevant data sets and remove irrelevant data
- Data preparation: Data engineers pre-process and clean the data to improve quality and remove “noise”
- Data transformation: Data engineers transform the data into a format suitable for machine learning analysis
- Data mining: Data engineers run the data through one or more machine learning or NLP models to extract relevant insights
- Analysis of results: Data miners examine results and fine-tune models to determine validity and business relevance
- Assimilation of knowledge: Data miners prepare reports explaining the insights derived and their business value
This sequence broadly follows CRISP-DM, the Cross-Industry Standard Process for Data Mining published in 2000. Its six phases are business understanding, data understanding, data preparation, modeling, evaluation and deployment. CRISP-DM makes explicit what the list leaves implicit: agreeing on the business question first, then deploying the model so its results reach the people who act on them.
In a cloud stack, steps 1 to 4 are usually automated. Connectors such as Fivetran and Airbyte handle ingestion, while SQL models in dbt handle selection, cleaning and transformation, with tests that run on every build. Analysts and data scientists can then spend their time on steps 5 to 7.
Data Mining Inside a Modern Cloud Data Warehouse
Data mining is an extremely valuable activity for data-driven businesses, but also very difficult to prepare for. Data has to go through a long pipeline before it is ready to be mined, and in most cases, analysts or data scientists cannot perform the process themselves. They have to request data from IT or data engineers and “wait in line” until the data is cleaned and prepared.
This was true for traditional data warehouses. Cloud data warehouses now take care of much more than storing the data and facilitating queries: many of them can train and run models where the data already lives, so analysts can mine data with SQL instead of waiting for an export.
- BigQuery ML: In Google BigQuery, a CREATE MODEL statement trains models in SQL. Supported types include linear and logistic regression, k-means clustering, boosted trees, matrix factorization and ARIMA_PLUS time-series models.
- Amazon Redshift ML: In Amazon Redshift, CREATE MODEL sends training data to Amazon SageMaker Autopilot, which picks and trains a model. It then returns the model as a SQL function for predictions.
- Snowflake ML Functions: Snowflake offers forecasting, anomaly detection, classification and top insights as SQL functions. Cortex AI functions add text analysis, including the extraction and summarization methods described above.
- Databricks: Databricks combines notebooks with MLflow for tracking experiments and models. Its AI Functions include ai_forecast and ai_query, which run from SQL.
Outside the warehouse, visual tools such as KNIME and Alteryx let analysts build mining workflows without writing code. Python notebooks remain the default for data scientists, while DuckDB is a common choice for working with an extract on a laptop.
Running models in the warehouse removes the export step and keeps data under the same access controls. It does not replace a clear business question or the validity checks required by the three principles above.
Common questions
Is data mining the same as machine learning?
No. Data mining is the goal of finding useful patterns in large data sets, while machine learning is a family of methods often used to reach that goal. Data mining also uses statistics, SQL queries and visual exploration, so it does not always require a machine learning model.
Do you need a data warehouse for data mining?
No. Data mining can run on a spreadsheet export, a database or files in a data lake. A warehouse helps because the data is already cleaned, combined from multiple sources and kept up to date, so you spend less time preparing it for analysis.
Can you do data mining with SQL?
Yes. SQL handles selection, aggregation and many association and sequence queries. BigQuery ML, Redshift ML, Snowflake ML Functions and Databricks AI Functions extend SQL with model training or prediction capabilities. Their supported methods differ, so the available analysis depends on which warehouse you use.
What is the difference between data mining and business intelligence?
Business intelligence reports on questions the business already asks, such as monthly revenue by region; data mining searches for patterns nobody asked about yet. The two can work together: BI dashboards often display data mining results, such as customer segments or churn scores.
What is CRISP-DM?
CRISP-DM is the Cross-Industry Standard Process for Data Mining, a six-phase model published in 2000. Its phases are business understanding, data understanding, data preparation, modeling, evaluation and deployment. Teams use it to plan data mining projects, from defining the business question to putting results into use.
Where to next
BI and Data Warehousing covers the reporting side of the warehouse, while The New EDW shows how the warehouse became a stack of layers. For the storage choice behind data mining, Data Warehouse vs. Data Lake explains the distinction. Data Warehouses compares the main cloud platforms.
Snowflake, BigQuery, Redshift, Databricks, Fivetran, Airbyte and the rest, with pricing and what each one replaces.
Browse the tools