Amperity is an enterprise customer data platform for consumer brands, built around Stitch identity resolution, a curated Customer 360, four predictive models, and integrations across 22 categories. Founded in Seattle in 2016, it now sells itself as an agentic “Customer Context Platform”, with a hosted MCP server that went GA in summer 2026 and an AI agent, Pér, that Amperity detailed on October 8, 2026 without an availability date.
In this Amperity review, I’ll take a closer look at Amperity’s pricing, features, and how it compares to Hightouch, Segment, mParticle and Treasure Data, so you can see exactly whether its identity resolution justifies a sales-led contract with no public rates.
Editor’s note: This Amperity review evaluates the pricing model, identity resolution, activation and AI features of Amperity as of October 2026. The core platform is sales-led with no trial, so this is a product evaluation, not a hands-on performance test. I weigh pricing transparency, identity resolution controls, activation breadth, AI features, buyer fit and vendor direction.
Quick verdict: I recommend Amperity for enterprise consumer brands in retail, hospitality, travel and financial services that have customer records scattered across many systems and data engineers to run the platform. The trade-off is buying blind: there are no public rates, consumption in Amps is hard to forecast, and the core platform has no self-serve trial.
Key Takeaways:
- Stitch gives every customer a persistent Amperity ID, with three run types and tunable match thresholds
- Standard and Enterprise run the same platform; Enterprise adds 24/7 support, priority SLAs and private training
- Pricing is consumption-based in Amps, quoted by sales, with up to 10% of unused Amps rolling over to the next term
- There is no free tier for the core platform; only the Chuck Data agent has a free research-preview tier
- Stitch runs take 20 minutes to 2 hours, and Pér has no availability date yet
Pros and Cons
Pros
- Stitch assigns a persistent Amperity ID, with Normal, Force refresh and Incremental match runs
- Bridge shares tables zero-copy with Databricks, Snowflake and BigQuery
- 4 predictive models: churn, event propensity, predicted CLV and product affinity
- Hosted MCP server is GA with OAuth and multi-user access
- 22 integration categories, now including Reddit Ads, Snapchat CAPI and Viant DSP
- AI Assistant builds segments and journeys from a conversation
Cons
- No published rates, and Amps consumption is hard to forecast
- No free trial for the core platform
- Standard support covers only 6 a.m. to 6 p.m. PT on weekdays
- Stitch runs take 20 minutes to 2 hours, so profiles refresh in batches
- Built for consumer brands, with no account-based B2B features
How Much Does Amperity Cost?
Amperity publishes no dollar rates. Pricing is usage-based in Amps, a standardized unit that covers processing customer records, building segments, running campaigns and activating insights, and Amperity’s team sizes each contract with an Amps calculator during the sales process. Both editions run the full platform and differ only in support and training.
- Standard (custom quote): for teams that can live with business-hours support, with the full platform, support from 6 a.m. to 6 p.m. PT Monday to Friday, and standard SLAs
- Enterprise (custom quote): for brands running Amperity as core infrastructure, adding 24/7 support, priority response SLAs, priority ticket reviews and private instructor-led training for marketers and operators
An Amps dashboard breaks consumption down by feature, period and instance (production or sandbox) and sends alerts at thresholds you set. Amp Insights, added in spring 2026, answers plain-language questions about usage.
- Overage: pay on-demand pricing, or buy additional Amps packages at better rates for the rest of the term
- Rollover: up to 10% of unused Amps from the initial contract can carry into the next term, and restrictions may apply
| Edition | Price | Usage basis | Support and extras | Who it fits |
|---|---|---|---|---|
| Standard | Custom quote | Amps | 6 a.m. to 6 p.m. PT weekdays, standard SLAs | Brands with in-house data staff and business-hours needs |
| Enterprise | Custom quote | Amps | 24/7 support, priority SLAs and ticket reviews, private training | Brands running Amperity as core customer infrastructure |
| Chuck Data (research preview) | Free | Unlimited Stitch runs up to 1M records | Terminal agent inside Databricks | Databricks teams previewing identity resolution |
Is Amperity Good Value for Money?
- Good fit: brands whose biggest data problem is duplicate and conflicting customer records, since Stitch, Customer 360, predictive models and activation replace several separate tools under one contract
- Hidden cost: record processing, segment builds, campaign runs and activations all draw down the same Amps balance, so I’d set threshold alerts in the Amps dashboard from the first month
- Less convincing fit: teams whose warehouse already holds well-modeled customer data; Hightouch activates directly from that warehouse at a lower cost of entry
- Forecasting risk: with no public rate card, I can’t compare Amperity against any rival on price until the calculator output arrives
Reviewer’s Notes: I’d start on Standard unless 24/7 support or private training for the marketing team is a hard requirement, since both editions run the same platform. Before signing, I’d get the Amps calculator output for a realistic year and negotiate the overage rate and rollover terms in writing, because Amperity notes that restrictions may apply to the 10% rollover.
Getting Started With Amperity
Amperity has no self-serve signup or trial, so access starts with a sales conversation and moves into a sales-led implementation with guided setup. Users report a learning curve during onboarding, so I’d name an internal owner for Stitch QA before kickoff.
Connecting Data Sources
Source connectors bring in data from upstream systems, while Amperity Bridge connects warehouse tables in Databricks, Snowflake or BigQuery zero-copy, without replicating them. A table only enters identity resolution if it is marked “Make available to Stitch” in the Feed Editor and then selected in Stitch settings, so this is where I’d decide which sources are trustworthy enough to shape the graph.
Running Stitch
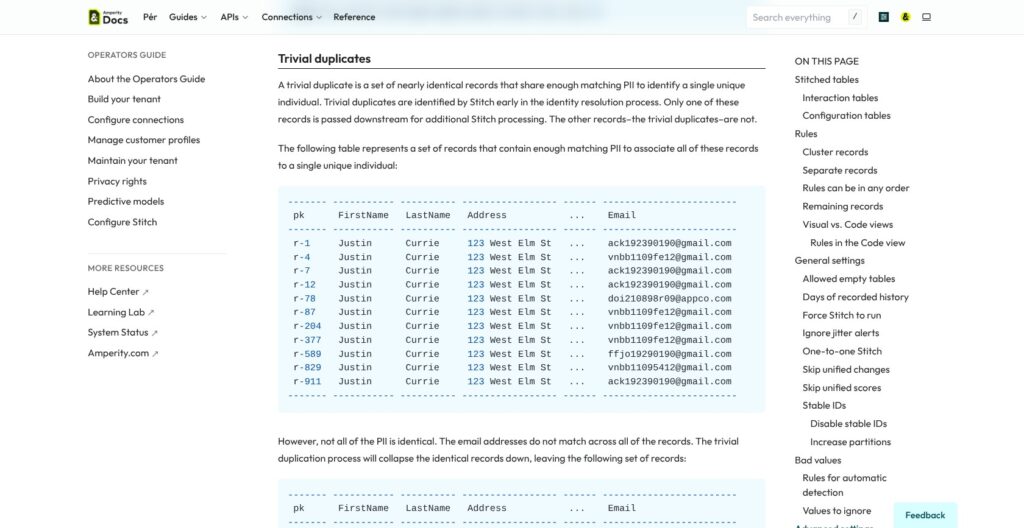
The Stitch settings dialog has a Stitched tables tab listing the feeds selected for matching. A run takes 20 minutes to 2 hours and comes in three types: Normal, Force refresh and Incremental match. The tunable settings are semantic tag handling, blocking strategy, match category thresholds and the maximum number of trivial duplicates. Leave them untouched until the first run finishes and Stitch QA has started.
Building a First Audience
Once Stitch produces Amperity IDs, audiences come from the segment editor, SQL queries or the AI Assistant, which builds a segment from a plain-language request. Segments then activate through campaigns, journeys or orchestrations that send to connected destinations.
Reviewer’s Notes: I’d be strict with the “Make available to Stitch” checkbox, because a low-quality source, such as a guest-checkout table full of shared or fake emails, pollutes the graph for every downstream segment. I’d start with the two or three sources I trust most and add the rest after the first Stitch QA round.
Identity Resolution and Customer 360
Stitch builds an identity graph across every source made available to it and assigns each resolved person a persistent Amperity ID, and that graph is the main reason to shortlist Amperity over event-first CDPs.
🧬 Stitch Identity Graph
Blocking strategy and match category thresholds decide how aggressively records merge, so a hotel group with shared family bookings can tune differently from a retailer with heavy guest checkout. Multi-brand businesses get a separate customer graph per brand rather than one merged pool. Amperity reports that Stitch resolved 3.4 million fragmented profiles for New Look, alongside 24% more high-value customers.
Hightouch activates from your own warehouse, so it works best when that warehouse already holds clean, modeled customer data, while Segment and mParticle are built around event collection from web and mobile SDKs. Amperity’s record-level matching suits brands whose messiest data sits in store, loyalty and service systems.
👤 Customer 360 and Profiles
Customer 360 turns the graph into curated tables for marketing, analytics, loyalty and operations, so each team works from a version shaped for its job instead of raw stitched records. Users report that Amperity’s SQL dialect follows Spark SQL conventions rather than the standard SQL their analysts already write, so I’d budget ramp-up time for whoever owns queries.
Predictive Models, Activation and Real-Time Profiles
Amperity ships four predictive models, so a brand without a data science team still gets churn and lifetime value scores.
📈 Predictive Models
- Churn propensity: flags customers likely to lapse
- Event propensity: predicts a chosen target event within a 30-day window
- Predicted CLV: forecasts customer lifetime value
- Product affinity: ranks the products each customer is most likely to buy
Since spring 2026, CLV and product affinity have a self-serve UI. Data science teams can take over training and versioning instead of using the out-of-box models.
📣 Audiences, Campaigns and Journeys
Amperity maps segments and queries to 9 common use cases, including churn prevention, direct mail, paid media, one-time buyers and RFM analysis. Summer 2026 added destinations for Reddit Ads, Snapchat CAPI and Viant DSP, plus Paid Media Measurement, which pulls Meta and Google ad performance back into Amperity. Audience Monetization, added in spring 2026, lets brands package and sell first-party audiences as UID 2.0 audiences in The Trade Desk Data Marketplace.
Native activation is narrower than in campaign-first CDPs like Redpoint, so complex orchestration may still belong in your email or journey tool.
⚡ Real-Time Profile API
The Profile API ties anonymous browsing to a known customer’s history, and Amperity describes delivery as “in milliseconds” without publishing a latency figure. I’d load-test it on my own site before promising real-time personalization to a web team.
AI Features: AI Assistant, Recommended Actions, MCP Server and Pér
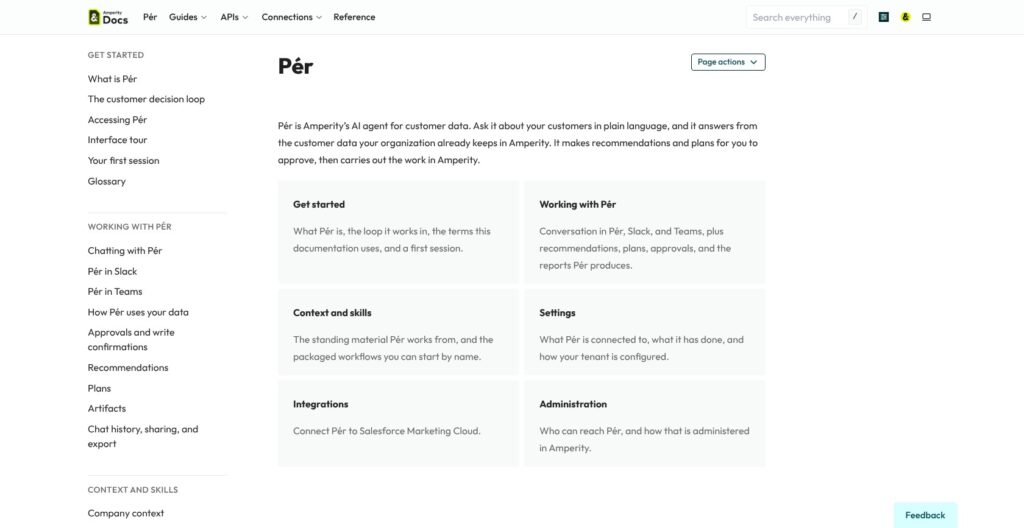
Amperity shipped the AI Assistant, Recommended Actions and a GA MCP server across spring and summer 2026; Pér is the only headline AI feature without a release date.
🤖 AI Assistant and Recommended Actions
The AI Assistant, added in spring 2026, builds segments, designs journeys and explores customer data through conversation. Recommended Actions, added in summer 2026, surfaces prioritized marketing plays with an expected business impact and turns any of them into a journey in one click.
🔌 MCP Server
The MCP server, announced in spring 2026, went GA in summer 2026 as a hosted, multi-user service with OAuth and an expanded tool set, giving external AI agents access to Amperity’s customer context. Bridge’s bring-your-own storage and compute keep the underlying data in your lakehouse. Because it is GA and built for external agents, this is the AI feature I’d put in front of an engineering team today.
🧭 Pér
Pér prepares audiences and actions from chat requests and acts inside Amperity only after you review and approve them. As detailed on October 8, 2026, it chats in the Pér app, Slack and Microsoft Teams, adds Company context, Memory, Skills and Artifacts, and integrates with Salesforce Marketing Cloud, but Amperity has given no availability date. I treat Pér as roadmap until it does.
🛠️ Chuck Data
Chuck Data, launched in June 2025, is a terminal AI agent for customer data engineering that runs inside Databricks and installs through Homebrew. Its free tier covers unlimited Stitch runs up to 1 million records during the research preview, so I’d use it to check Stitch’s match quality on a sample before the first sales call.
Security, Support and Integrations
Support depends on the edition: Standard covers 6 a.m. to 6 p.m. PT on weekdays, while Enterprise adds 24/7 coverage with priority SLAs. Amperity lists SOC 2, ISO 27001, HIPAA, GDPR and CCPA compliance.
- Warehouses and clouds: Snowflake, Databricks and Google BigQuery (all three via Bridge), plus Microsoft, Amazon and PostgreSQL
- Marketing and ad platforms: Salesforce, Klaviyo, Braze, Google, Meta, TikTok and Pinterest
- APIs: Amperity API, Profile API and Streaming API
Amperity names Wyndham, New Look, Alaska Airlines, Citizen Watch and BECU as customers. It reports a 60% conversion increase for Wyndham, a 198% loyalty conversion increase for Alaska Airlines, and 20+ hours a week saved at BECU with dashboards that refresh daily; Citizen Watch chose Amperity after evaluating 9 vendors. Users also report limited alerting when orchestrations fail, which I’d raise before signing.
How Does Amperity Compare to Competitors?
Amperity wins on identity resolution depth and zero-copy lakehouse sharing; it loses on price transparency and self-serve entry.
- Hightouch: best for warehouse-native teams. It is a reverse ETL tool and composable CDP with no-code and SQL audience building, and it wins when your warehouse already holds clean customer data and you want a lower cost of entry.
- Segment: best for product-led teams. Twilio’s event collection CDP suits web and app behavior better than offline store and loyalty records.
- mParticle: best for app-first brands. Rokt’s event and mobile SDK CDP handles in-app data that Amperity’s batch matching doesn’t target.
- Treasure Data: best for teams with strong data engineering, since it is a more engineering-heavy CDP to set up and run.
- Redpoint: best for campaign execution depth, which goes further than Amperity’s native activation.
| Tool | Best at | Pricing model | Pick it when |
|---|---|---|---|
| Amperity | Identity resolution on messy consumer records | Amps consumption, sales quote | Many conflicting customer sources and data engineers on staff |
| Hightouch | Warehouse-native activation | Free tier, then paid | Your warehouse already holds clean customer data |
| Twilio Segment | Event collection | Free tier, then paid | Web and app events drive your stack |
| mParticle | Mobile event pipelines | Sales quote | Your customers live in apps |
| Treasure Data | Engineering-led CDP builds | Sales quote | Your data engineers want to own the build |
| Redpoint | Campaign execution | Sales quote | Orchestration depth matters most |
Pick Amperity if identity quality across store, loyalty and digital sources is the core problem; pick Hightouch if your warehouse is already the source of truth; pick Segment or mParticle if event streams matter more than record-level matching.
How I Reviewed Amperity
I judged Amperity on the six areas named in the Editor’s note: pricing transparency, identity resolution controls, activation breadth, AI features, buyer fit and vendor direction.
For identity, I went through Stitch’s run types, settings and QA order, Bridge sources for Databricks, Snowflake and BigQuery, and Customer 360. For activation, I mapped the four predictive models, segments, queries, campaigns, journeys, the Profile and Streaming APIs, and the 2026 destinations. For AI, I separated what has shipped (AI Assistant, Recommended Actions, the MCP server, Chuck Data) from what is announced (Pér). For pricing, I worked through Amps, overage, rollover and the two editions, then compared the model with Hightouch, Segment, mParticle, Treasure Data and Redpoint.
The core platform is sales-led with no trial, so this is an evaluation of what Amperity ships and publishes, not a hands-on performance test, and I make no claims about match accuracy or speed on my own data.
Prices current as of October 2026.
Should You Choose Amperity as Your CDP?
Yes, if you’re an enterprise consumer brand with customer records spread across store, ecommerce, loyalty and service systems, a data engineering team, and a Databricks or Snowflake warehouse. Stitch’s tunable matching, Customer 360 and zero-copy Bridge add up to a deeper identity layer than event-first CDPs like Segment and mParticle.
Skip it if you’re a small business, sell B2B with account-based motions, run on one or two clean systems, or need published prices before a first call. Composable teams with a mature warehouse should price Hightouch first.
My next step would be to ask Amperity for the Amps calculator output on a realistic year, negotiate overage and rollover terms before signing, and have the implementation run Stitch first on a sample of my highest-conflict sources, so I see match quality before committing every feed. Databricks teams can preview Stitch on up to 1 million records free through Chuck Data.
FAQs
Is Amperity a CDP?
Yes. Amperity is an enterprise customer data platform for consumer brands that unifies records with Stitch identity resolution, builds a Customer 360, scores customers with four predictive models and connects to integrations across 22 categories. It now markets itself as an agentic “Customer Context Platform”, adding a hosted MCP server and the Pér agent on the same CDP core.
How much does Amperity cost?
Amperity publishes no dollar rates. Pricing is usage-based in Amps and quoted by sales, with two editions on the same platform: Standard (business-hours support) and Enterprise (24/7 support, priority SLAs, private training). Overage runs on-demand or through extra packages, and up to 10% of unused Amps can roll over. See How Much Does Amperity Cost? above for the full breakdown.
What is Amperity Stitch?
Stitch is Amperity’s identity resolution engine. It matches records from every source marked “Make available to Stitch”, builds an identity graph and assigns each person a persistent Amperity ID. Runs take 20 minutes to 2 hours, come in Normal, Force refresh and Incremental match types, and use adjustable blocking strategy and match category thresholds.
Does Amperity work with Snowflake and Databricks?
Yes. Amperity Bridge shares tables zero-copy with Snowflake, Databricks and Google BigQuery, so data doesn’t have to be replicated into Amperity, and bring-your-own storage and compute keep the platform lakehouse native. Chuck Data, Amperity’s terminal agent, also runs inside Databricks.
Is there a free version of Amperity?
No, not for the core platform, and there’s no self-serve trial. The only free option is Chuck Data, a terminal agent inside Databricks whose research-preview free tier covers unlimited Stitch runs up to 1 million records.
Is Pér available?
Not on a confirmed date. Amperity detailed Pér on October 8, 2026 as an agent that prepares audiences and actions, waits for your approval and then acts in Amperity, with chat in Slack and Microsoft Teams, but gave no availability date. The MCP server and AI Assistant are the shipped AI features today.