Editor’s note: In this ClearML review, I evaluate pricing transparency, adoption signals, development momentum, openness and exit costs, and practitioner feedback. My assessment is based on research and documented user experiences, not a hands-on performance test.
Quick verdict: I recommend ClearML for teams that want tracking, dataset versioning, and GPU orchestration in one Apache-2.0 platform at about a third of W&B’s seat price. The trade-offs: governance tooling (explainability, feature store, bias detection) is DIY, and self-hosted upgrades carry a documented corruption risk.
Key Takeaways 🔍
- ClearML Pro costs $15/user/month, roughly a third of Weights & Biases’ cited seat price (verified September 2026)
- The core is Apache-2.0; self-hosting runs unlimited experiments free; the real cap is 3 team members
- Independent scorecards split it cleanly: best-in-class tracking, data versioning, and GPU orchestration; DIY explainability, feature store, data quality, and bias detection
- One self-hosted upgrade (1.15 to 2.0) corrupted the database, losing console output and metric graphs
- Independent sentiment is thin: one scorecard caps its confidence at 37% on 13 G2 reviews
ClearML interests me because it brings tracking, data versioning, orchestration, and serving into one product. In this review, I’ll look at where that breadth offers real value and where I’d still budget for separate tooling.
Pros and Cons
I like ClearML’s breadth and low seat price. My main reservations are its governance gaps and interface polish.
Pros
- Auto-instrumentation logs hyperparameters, metrics, console output, and git diffs across PyTorch, TensorFlow, Keras, XGBoost, scikit-learn, and Hugging Face
- Native GPU orchestration: Agents and Queues, fractional GPUs (MIG), automated spot management on AWS, GCP, and Azure
- Built-in dataset versioning with parent-child lineage
- Apache-2.0 core; the self-hosted free tier runs unlimited experiments
- Pro is $15/user/month, roughly a third of W&B’s cited seat cost
Cons
- Free tier caps at 3 team members, hosted or self-hosted
- Explainability, feature store, data quality, and bias detection rate DIY on an independent capability scorecard
- One documented self-hosted upgrade corrupted the database, losing console output and metric graphs
- Plots fail to render in some browsers; graphs trail W&B’s polish (hands-on account)
- No SQL interface; Snowflake and BigQuery connectors are custom-script territory
How Much Does ClearML Cost?
ClearML pricing spans four tiers, verified against the vendor’s pricing page in September 2026:
- Community ($0): 3 team members, 100GB of artifact storage, 1GB of metric events, and 1M API calls per month on the hosted version. The self-hosted variant runs full platform features with unlimited experiments but keeps the 3-member cap.
- Pro ($15/user/month): up to 10 team members, with 120GB of storage, 1.2GB of metric events, and 1.2M API calls per month included.
- Scale (custom quote): for organizations running 8-48 GPUs on VPC-only infrastructure.
- Enterprise (custom quote): VPC or on-premises clusters running multiple large projects, adding a config vault, Slurm/PBS integration, LDAP, RBAC, and dynamic fractional GPUs.
| Tier | Price | Team members | Storage | Metric events | API calls |
|---|---|---|---|---|---|
| Community | $0 | 3 | 100GB | 1GB | 1M/month |
| Pro | $15/user/month | Up to 10 | 120GB | 1.2GB | 1.2M/month |
| Scale | Custom quote | Custom | Custom | Custom | Custom |
| Enterprise | Custom quote | Custom | Custom | Custom | Custom |
Past the included quotas, Pro bills $0.10 per GB of storage, $0.01 per MB of metric events, $1 per 100,000 API calls, and $0.04 per hour per application.
A gigabyte of metric events past the 1.2GB allowance costs about $10.24 (1,024MB at $0.01), while a gigabyte of extra artifact storage costs $0.10. With that roughly 100x gap, I’d estimate logging volume before committing a team, rather than judging the cost by seats alone.
Is ClearML Good Value for Money?
- Against Weights & Biases, the cited $50+/user/month seat cost makes ClearML Pro roughly a third of the price, and W&B ships no native orchestration or dataset versioning at that price
- Against Comet, whose MLOps Pro plan lists at $19/user/month on its pricing page (September 2026), ClearML Pro is $4 cheaper per seat and bundles orchestration Comet leaves external
- Against MLflow, the software is free either way; MLflow’s cost is assembly, since you pair it with an external orchestrator and data-versioning tooling and run the infrastructure yourself
- The self-hosted escape hatch is real value: Apache-2.0, unlimited experiments, no per-seat bill
- The cost risk is the metric-events meter for logging-heavy training, not the sticker price
For a full 10-person Pro team, that works out to $150/month in seats on ClearML, against $190 on Comet and $500+ on Weights & Biases, before any overages.
Reviewer’s Notes
I’d start on the hosted free tier: there is no infrastructure to stand up, and the 3-member cap tells you quickly whether you have outgrown it. I’d only self-host with the upgrade discipline I cover below. Before moving a team of ten to Pro, I’d price the $0.01/MB metric meter against actual logging volume; that line item is my main budget concern.
— Panoply reviewer
Getting Started With ClearML
I’d start with ClearML’s auto-logging: its promise of instrumenting a training script with two lines of code is the quickest way to assess whether the tracking workflow suits your team.
Auto-Logging a Training Run
Adding Task.init() to a training script hooks ClearML into PyTorch, TensorFlow, Keras, XGBoost, scikit-learn, and Hugging Face, and the run’s hyperparameters, metrics, console output, and git diff land in the web UI without a single manual logging call. For me, that automatic baseline is the platform’s strongest onboarding argument.
One caveat from the published hands-on writeup: PyTorch Lightning metrics are not always captured automatically, so Lightning teams should spot-check their first runs rather than trusting the dashboard blind. The same writeup notes that plots and debug images will not display in some browsers and calls the mobile version inconvenient, so keep a desktop browser handy for run comparisons.
Versioning a Dataset
The dataset flow runs through the CLI or the Python SDK: create a dataset, add files, then finalize it to register a version. Child datasets hold augmented or merged variants while preserving parent-child lineage, and get_local_copy() pulls a cached working copy wherever the training runs, with cache management handled by the SDK. One documented warning: deleting a parent dataset can cause data loss in datasets merged from it, so treat finalized parents as permanent.
Self-Hosting: Read Before Upgrading
The self-hosted server installs from the official docker-compose configuration. Running it is not the risk; upgrading it is. One team that moved a self-hosted server from 1.15 through 1.17 to 2.0 on the official upgrade path ended with a database that did not migrate correctly: experiments still listed in the overview, console output and metric graphs gone. An older report, from 2021, described a clean install finishing without errors yet missing parts of the web UI, including any option to create credentials.
My recommendation from those reports is to snapshot the database before any server upgrade and rehearse the upgrade on a staging copy first. The rehearsal is cheap next to the alternative, which cost one team its console history and metric graphs.
Users describe the documentation as still maturing, with mixed feedback on its quality, and the community is smaller than MLflow’s, so the clearml-server GitHub issues are often where answers to self-hosting problems live.
Reviewer’s Notes
The sequence I’d recommend is the hosted free tier first, since there is nothing to stand up, followed by auto-logging for an immediate baseline. I’d consider docker-compose self-hosting once the workflow fits, then move on to pipelines. Orchestration is where I see ClearML’s biggest advantage over lightweight trackers, so I’d give that stage more time.
— Panoply reviewer
Orchestration and GPU Management: The Real Differentiator
For me, the Agents and Queues layer is ClearML’s clearest advantage over standalone trackers. Install the ClearML agent on any machine (a workstation, an on-prem box, a cloud instance) and it becomes a worker that pulls queued jobs; the scheduler handles fractional GPU splitting through MIG and manages spot instances automatically across AWS, GCP, and Azure. Fractional GPUs let several jobs share one physical card instead of idling it.
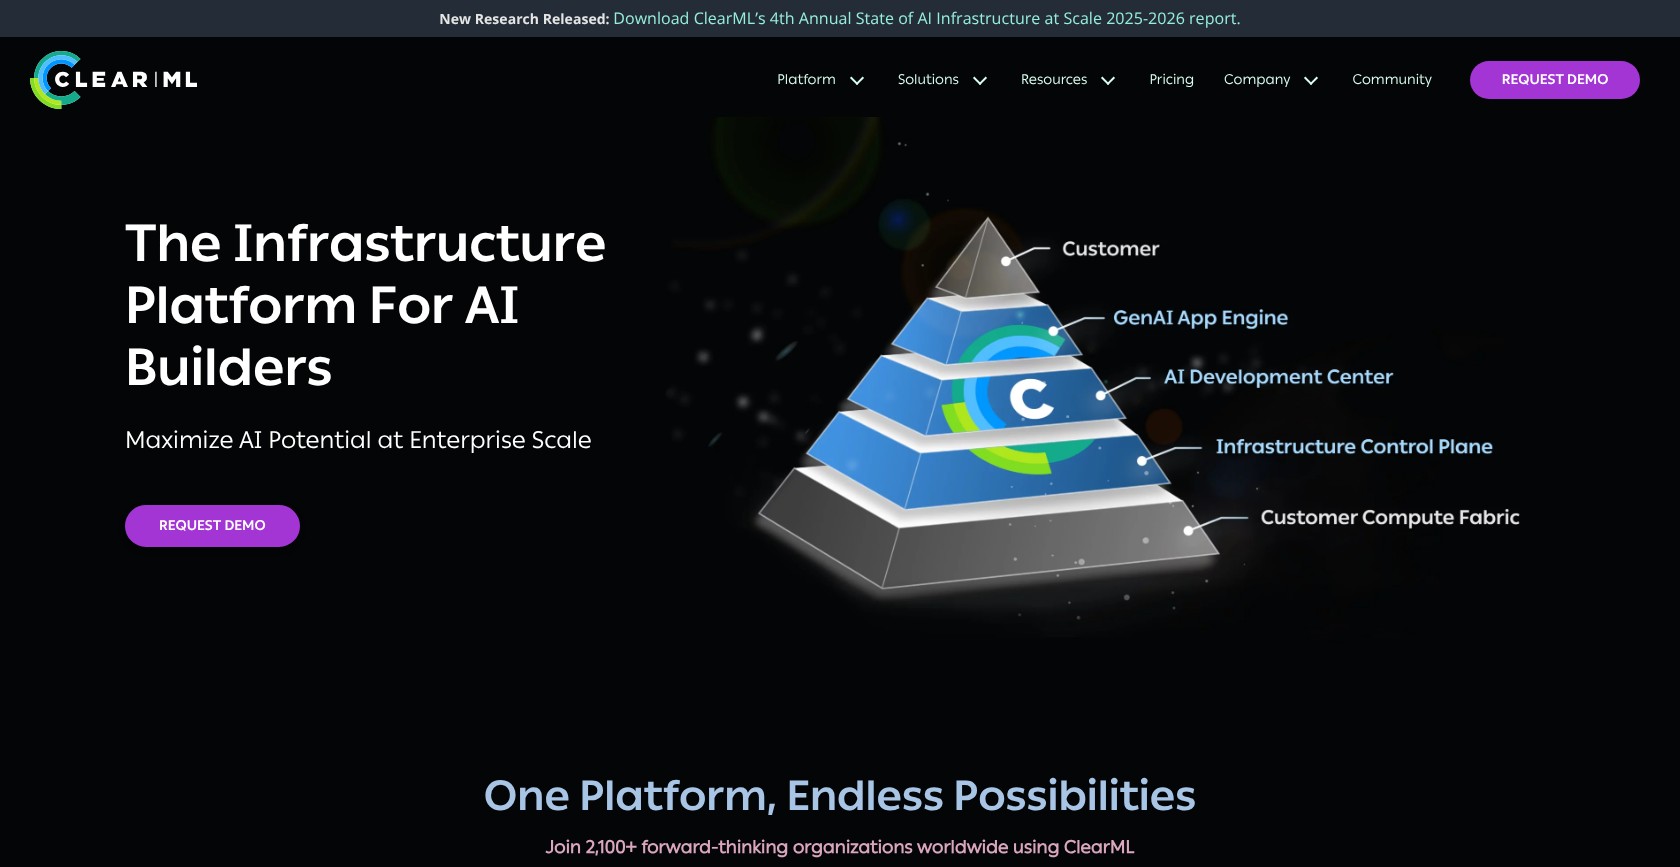
Both independent scorecards rate this the platform’s strongest territory: the procurement scorecard at rfp.wiki puts infrastructure and GPU management at 4.6/5 (pipeline orchestration scores the same), and productowl.io’s capability scorecard rates GPU acceleration best-in-class. The vendor’s own architecture frames the product in three layers (an Infrastructure Control Plane, an AI Development Center, and a GenAI App Engine), and orchestration is the bottom layer everything else stands on. One vendor-curated customer quote points the same direction: an algorithm developer at Saips credits ClearML with solving “our GPU compute management problem thanks to resource allocation, automation frameworks, and much more.”
I’d check the tier carefully, though: dynamic fractional GPUs and Slurm/PBS integration sit in the Enterprise tier, so the full scheduling surface is a custom-quote conversation, as covered in the pricing section above.
The counterpoint comes from a competitor: ZenML’s published comparison (competitor-authored, weigh it accordingly) argues that adopting ClearML’s orchestration layer trades convenience for coupling, since your scheduling then lives inside one vendor’s stack. I share that concern. For a team without a dedicated platform group, though, I’d still consider this layer a reason to pick ClearML over MLflow plus glue scripts: queues, GPU sharing, and spot management arrive configured rather than built.
Where the Scorecards Say It’s Thin
I’m less convinced by the end-to-end pitch when it comes to governance. productowl.io rates ClearML capability by capability on a 0-4 scale, and rfp.wiki’s 5-point procurement scorecard puts its lowest marks in the same corner:
- Model explainability, feature store, data quality validation, and bias detection all score 1/4 (DIY, manual workaround) on productowl.io’s capability scale
- SQL interface: 0/4, not supported; Snowflake and BigQuery connectors: 1/4, custom scripts required, which leaves most non-S3 warehouse data behind a scripting job
- rfp.wiki’s procurement scorecard shows the same shape from a different method: feature store at 3.5/5 and AutoML at 3.8/5, against 4.8/5 for experiment tracking
The practical answer, per the capability scorecard’s own guidance, is third-party integration: SHAP or LIME for explainability, Great Expectations for data quality, Fairlearn for bias detection. I’d include those integrations in the adoption budget from the start.
Serving is shakier than the module list suggests: the published hands-on account reports launch problems and version mismatches while assembling the ClearML Serving component, so I’d treat serving as a pilot project rather than a drop-in.
One more finding, about the evidence itself: rfp.wiki caps its own confidence in its ClearML scores at 37%, because only 13 G2 reviews existed to work from, and G2’s and SourceForge’s listing pages showed zero published reviews as of September 2026. Independent sentiment on ClearML is scarce, and that scarcity is information: you are adopting a platform with a small public track record, whatever the feature list says.
Adoption and Momentum
The verifiable signals: 6.9k GitHub stars and 802 forks on the main repository, and an active release cadence, with v2.1.12 shipped to PyPI on August 19, 2026. The PyPI package lists five modules: Experiment Manager, orchestration, data management with version control, model serving with GPU support, and Reports. The project was formerly Allegro Trains before rebranding, so its history runs longer than the ClearML name suggests.
The homepage claims 2,100+ organizations and 300,000+ AI Builders; a vendor-supplied listing elsewhere cites 150,000 data scientists and engineers. I would treat those inconsistent figures as marketing claims, not a reliable measure of adoption. The customer logos (NVIDIA, Meta, Tencent, Intel, Bosch, NYU) are vendor-listed, and the circulating customer quotes are vendor-curated: Theator’s CTO describes ClearML integrating “naturally” into the team’s process, and a senior data scientist at Daupler describes a loop of finding better data, labeling it, training, and comparing against production.
I’m more confident in the evidence for active development than in the claimed scale of adoption. That matches the thin independent review base from the previous section.
How Does ClearML Compare to Competitors?
My shortlist of ClearML alternatives depends on what you need most. Here’s where I’d consider each rival:
- MLflow: the tracking and registry standard, free and fully open source, with a larger ecosystem than ClearML’s. It ships no native orchestration and no native data versioning, so you pair it with Airflow or Kubeflow for scheduling and DVC for data, and reproducibility depends on your own tooling and discipline rather than platform guarantees. The choice is bundled breadth versus assemble-it-yourself.
- Weights & Biases: the polish leader, with the visualizations and UI refinement the hands-on account concedes ClearML trails. At $50+/user/month, roughly three times ClearML Pro, it also skips native orchestration and dataset versioning.
- Comet: the closest per-seat rival at $19/user/month for MLOps Pro (up to 10 members, 1,500 training hours, 500GB storage), pairing experiment tracking with production model monitoring in its Enterprise tier. Its core MLOps SDK is closed source, so self-hosting means an Enterprise license rather than a free Apache-2.0 server like ClearML’s.
- ZenML: not a tracker but an orchestration framework, infrastructure-agnostic through swappable Stack Components, with reproducibility enforced through versioned Pipeline Snapshots and containerized execution across local, Airflow, and Kubernetes backends. It pairs with a tracker rather than replacing one, and its published ClearML comparison is competitor-authored; read it as a rival’s brief.
- Neptune.ai: no longer on the board. OpenAI announced the acquisition on December 4, 2025, and Neptune’s standalone hosted service and API shut down on March 5, 2026.
I’d choose ClearML for a budget platform covering tracking, GPUs, and data. I’d favor MLflow for its registry and ecosystem if I were comfortable assembling the surrounding tools, and Weights & Biases if dashboard polish mattered most. If portability were my priority, I’d consider ZenML with a separate tracker.
How I Reviewed ClearML
My assessment draws on ClearML’s documented features and pricing, public repository and release data, independent capability scorecards, and published user reports. I use those sources to compare its tracking, dataset versioning, orchestration, and deployment trade-offs with the alternatives covered above. I have not run a hands-on ClearML performance test; the upgrade failures and interface issues described here come from published accounts.
I give limited weight to small review samples: 13 G2 reviews are not enough to determine my verdict. I also distinguish vendor adoption claims from independently supported signals. The pricing figures in this review reflect the September 2026 research.
ClearML Review: Should You Run Your ML Stack on ClearML?
So, is ClearML worth it? For the right team, yes. I recommend ClearML for teams managing their own GPUs who want tracking, dataset versioning, and orchestration in one Apache-2.0 platform at $15/user/month, and for self-hosters willing to bring upgrade discipline (database snapshot first, staging rehearsal always).
I wouldn’t choose ClearML if you need native governance tooling; explainability, bias detection, and the feature store all rate DIY on the capability scorecard, and the feature store also scores lowest on the procurement scorecard. I’d also look elsewhere if maximum UI polish mattered most (that is Weights & Biases territory) or if you want the largest community and ecosystem behind your tracker (that is MLflow). The scorecard pattern from earlier carries the whole verdict: best-in-class where GPUs and experiments meet, DIY where governance lives.
My suggested next step is to try the hosted free tier with auto-logging on one training script; the 3-member cap costs nothing to test under. If you manage GPUs, I’d also try an Agent on a spare machine. The orchestration layer is where ClearML earns its keep, and it is the layer tracking-first rivals like MLflow and Weights & Biases do not ship natively.
FAQ
Is ClearML really free for unlimited experiments?
Yes on experiments, with a team-size catch. The self-hosted Community tier has no experiment cap and includes full platform features, but both hosted and self-hosted free tiers stop at 3 team members. A fourth person means Pro at $15/user/month (up to 10 users) or a custom Scale or Enterprise quote.
What is the difference between ClearML and MLflow?
ClearML bundles orchestration (Agents and Queues), dataset versioning, and serving into one platform; MLflow deliberately stays a tracking and registry layer you pair with an external orchestrator like Airflow or Kubeflow. The trade is breadth with more coupling (ClearML) against simplicity with more assembly (MLflow). ZenML’s competitor-authored comparison frames that coupling as lock-in risk.
Can you self-host ClearML in production?
Yes. The core is Apache-2.0, installs via the official docker-compose configuration, and releases actively (v2.1.12 shipped August 2026). Bring upgrade discipline: one documented upgrade from 1.15 to 2.0 corrupted the database, so snapshot before every server upgrade and rehearse on staging. See Getting Started With ClearML above for the full case.
Where does ClearML fall short?
productowl.io’s capability scorecard rates model explainability, feature store, data quality validation, and bias detection DIY, scores the SQL interface as unsupported, and says Snowflake and BigQuery connectors need custom scripts; rfp.wiki’s lowest marks land on feature store (3.5/5) and AutoML (3.8/5). The published hands-on account adds plots that fail to render in some browsers and a Serving module with assembly problems.
Is Neptune.ai still a ClearML alternative?
No. OpenAI announced its acquisition of Neptune.ai on December 4, 2025, and Neptune’s standalone hosted service and API shut down on March 5, 2026, with remaining data deleted after that date. Teams cross-shopping ClearML should compare MLflow, Weights & Biases, Comet, or ZenML instead.